🗑️ scraps v2 (Octominer X12 Ultra)
scraps v2 (completed October 26, 2026; expanded to 5 GPUs November 1, 2026) is the 5-GPU Ada/Ampere folding server housed in the Octominer X12 Ultra 12-slot server chassis. Originally brought online as scraps v1 on the legacy Haswell i7-4790 / 8GB DDR3 AX-B85M-ETH ("GPNE") mining frame, scraps v2 inherited the Octominer X12 Ultra platform when smallpieces v3 migrated onto its AMD Ryzen 9 9900X + PCIe Gen 5.0/4.0 x4 platform—retiring its two legacy Turing cards and combining a ZOTAC GeForce RTX 4070 Blower in CPU-direct Slot 1 (Gen3 x16) with a ZOTAC GeForce RTX 3070 in Slot 2 (Gen3 x1) and three GeForce RTX 3060 Ti cards in Slots 4, 7, and 10.
🖥️ Hardware Summary (scraps v2 — Live Since Oct 26, 2026; 5-GPU Expansion Nov 1, 2026)
- Chassis & Cooling: Octominer X12 Ultra 12-Slot Server Chassis with high-static-pressure Delta fan wall (closed-loop PWM + CPU thermal-assist control via
octoctl v2.2.15) & Thermalright AXP90-X36 CPU cooler - Motherboard & CPU: Octominer B250 Custom Board + Intel Core i7-7700 (Kaby Lake 4-Core / 8-Thread; unlocked via
nvpowerctl v1.3.4clearing MSR0x1a0bit 38 with3.00 GHzsweet-spot ceiling & per-threadFahCoreCPU affinity isolation) - System Memory (RAM): 32GB DDR3L-1600 SODIMM (2x 16GB,
OPENMM_CPU_THREADS=4) — 4x upgrade over v1's 8GB ceiling (0.00 KB/sswap) - Network Interface: Onboard Realtek RTL8105E Fast Ethernet (
100baseT/Full,100 Mbps/~11.2 MB/swire speed onenp3s0) - Power Infrastructure: 4x HPE 750W Platinum Plus 240V Server PSUs (3000W total capacity, direct riserless motherboard busbars)
- OS, Kernel & Driver: Ubuntu 26.04.1 LTS | Linux Kernel
7.0.0-42-generic| NVIDIA Driver595.91.07(CUDA 13.2) - Current GPUs (5 Active Ada/Ampere GPUs —
20.20M PPDNov 1 baseline; tuned Nov 10 to725Wcap /674.5Wreal draw for+472klike-for-like PPD [~20.6M–21.5M PPD] &52°CRTX 3070): 1x ZOTAC GeForce RTX 4070 Blower (12GB, Slot 1 Gen3 x16,160Wcap,65%fan floor viagpufanpin v1.3.1) + 1x ZOTAC GeForce RTX 3070 (8GB, Slot 2 Gen3 x1,145Wcap,65%fan floor viagpufanpin v1.3.1) + 3x GeForce RTX 3060 Ti (8GB, Slots 4, 7, 10 Gen3 x1,140Wcap) —725Wcombined GPU power cap (160, 140, 145, 140, 140) - Retired Hardware (
scrapsv1): Intel Core i7-4790 + 8GB DDR3 AX-B85M-ETH board, 1x ASUS RTX 2060 (6GB, UUID535ba65c), and 1x Gigabyte RTX 2060 SUPER (8GB, UUID8990101d)
scraps v2.0 Glamour Shots (Octominer X12 Ultra Array & Chimney Exhaust • Era 13)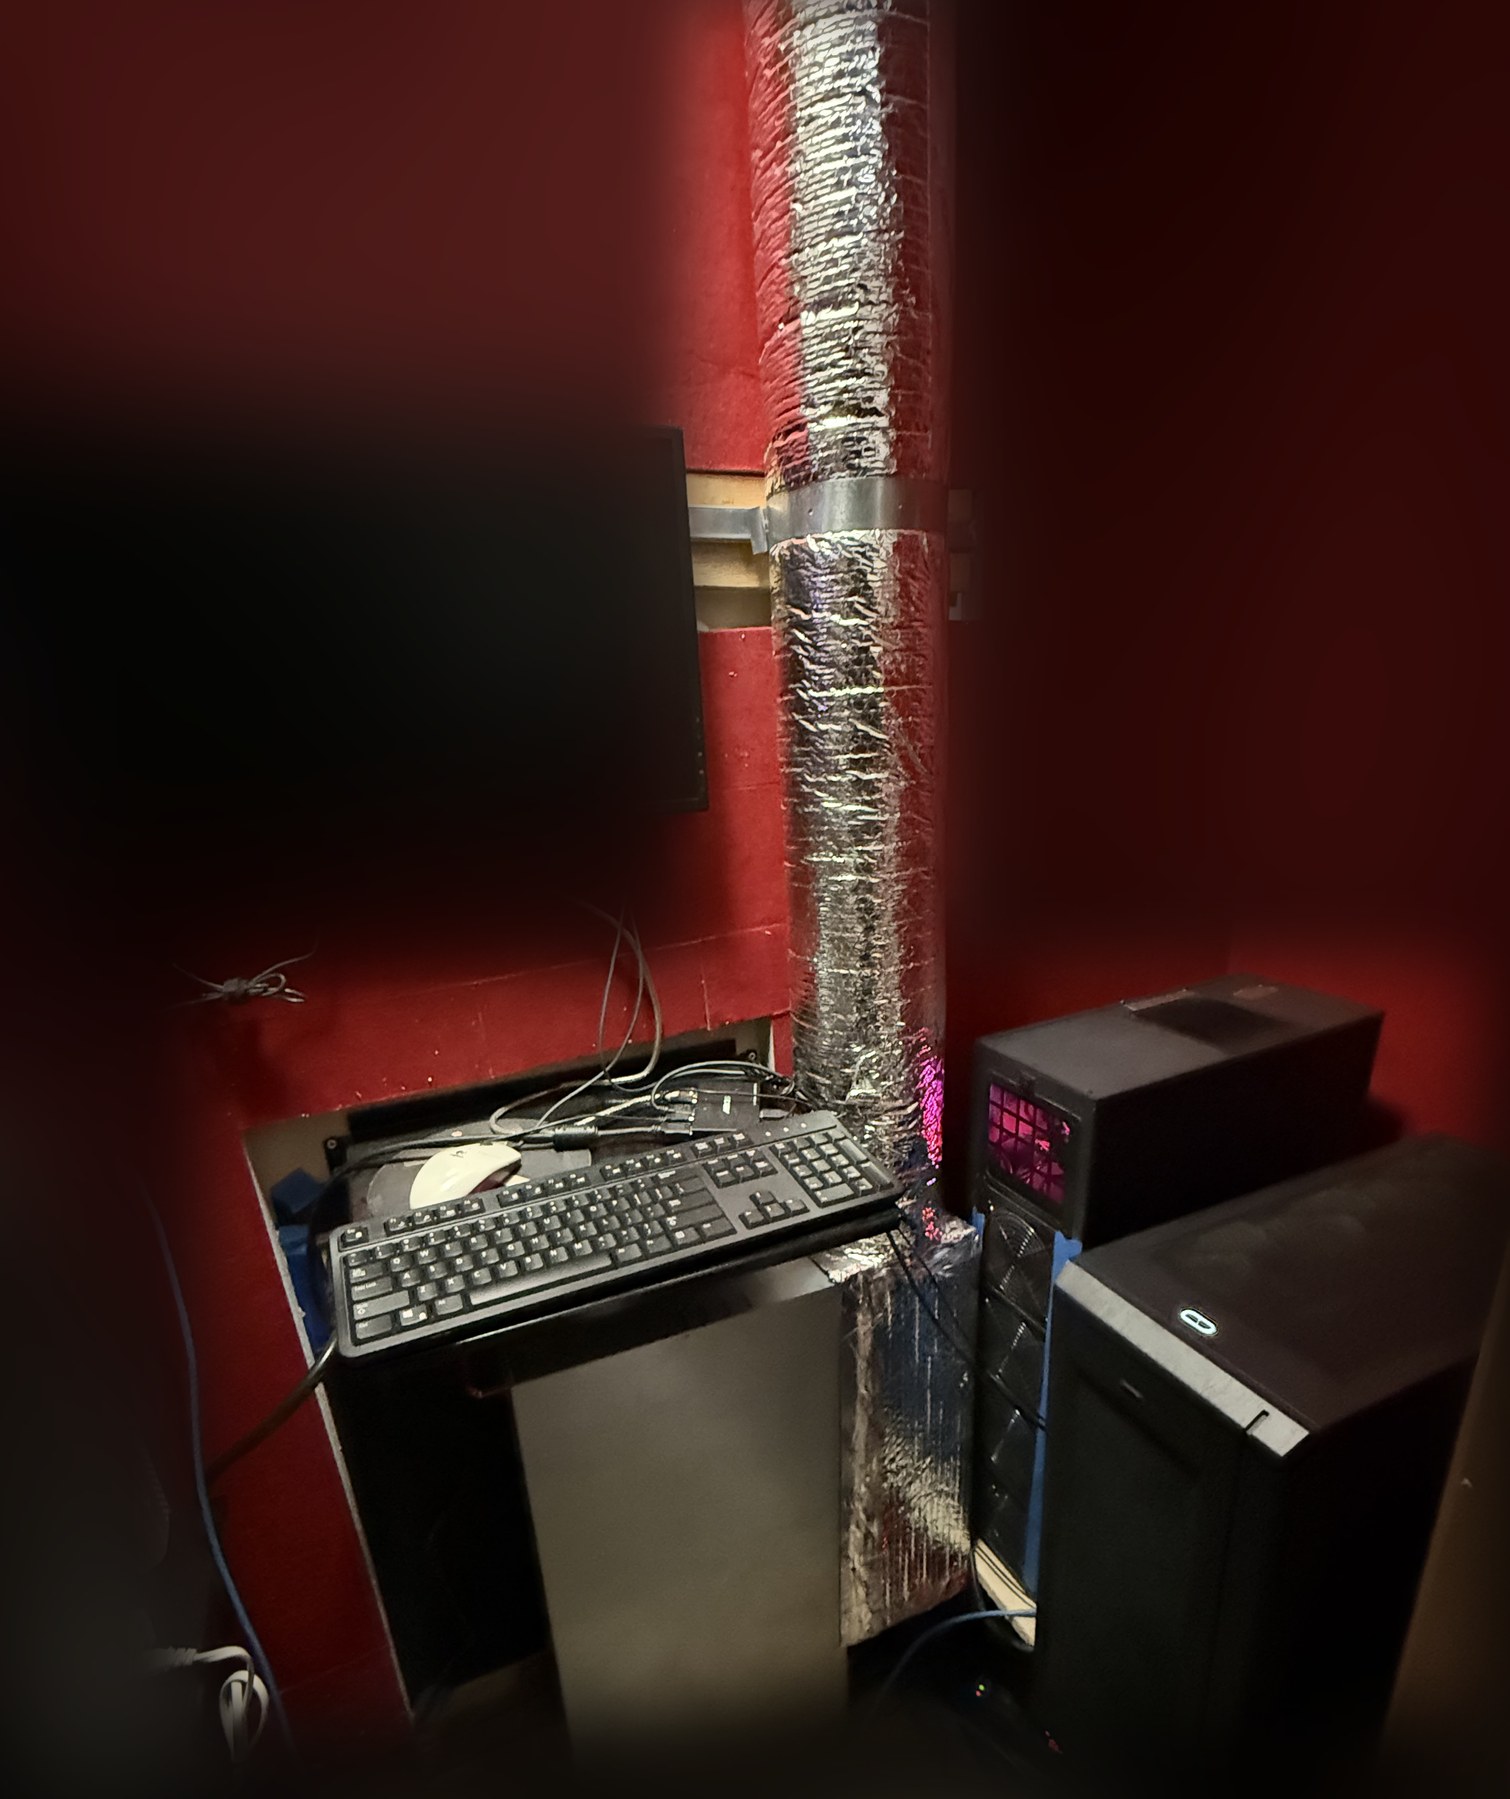 Era 13 • Oct 26+
🔍 Embiggen
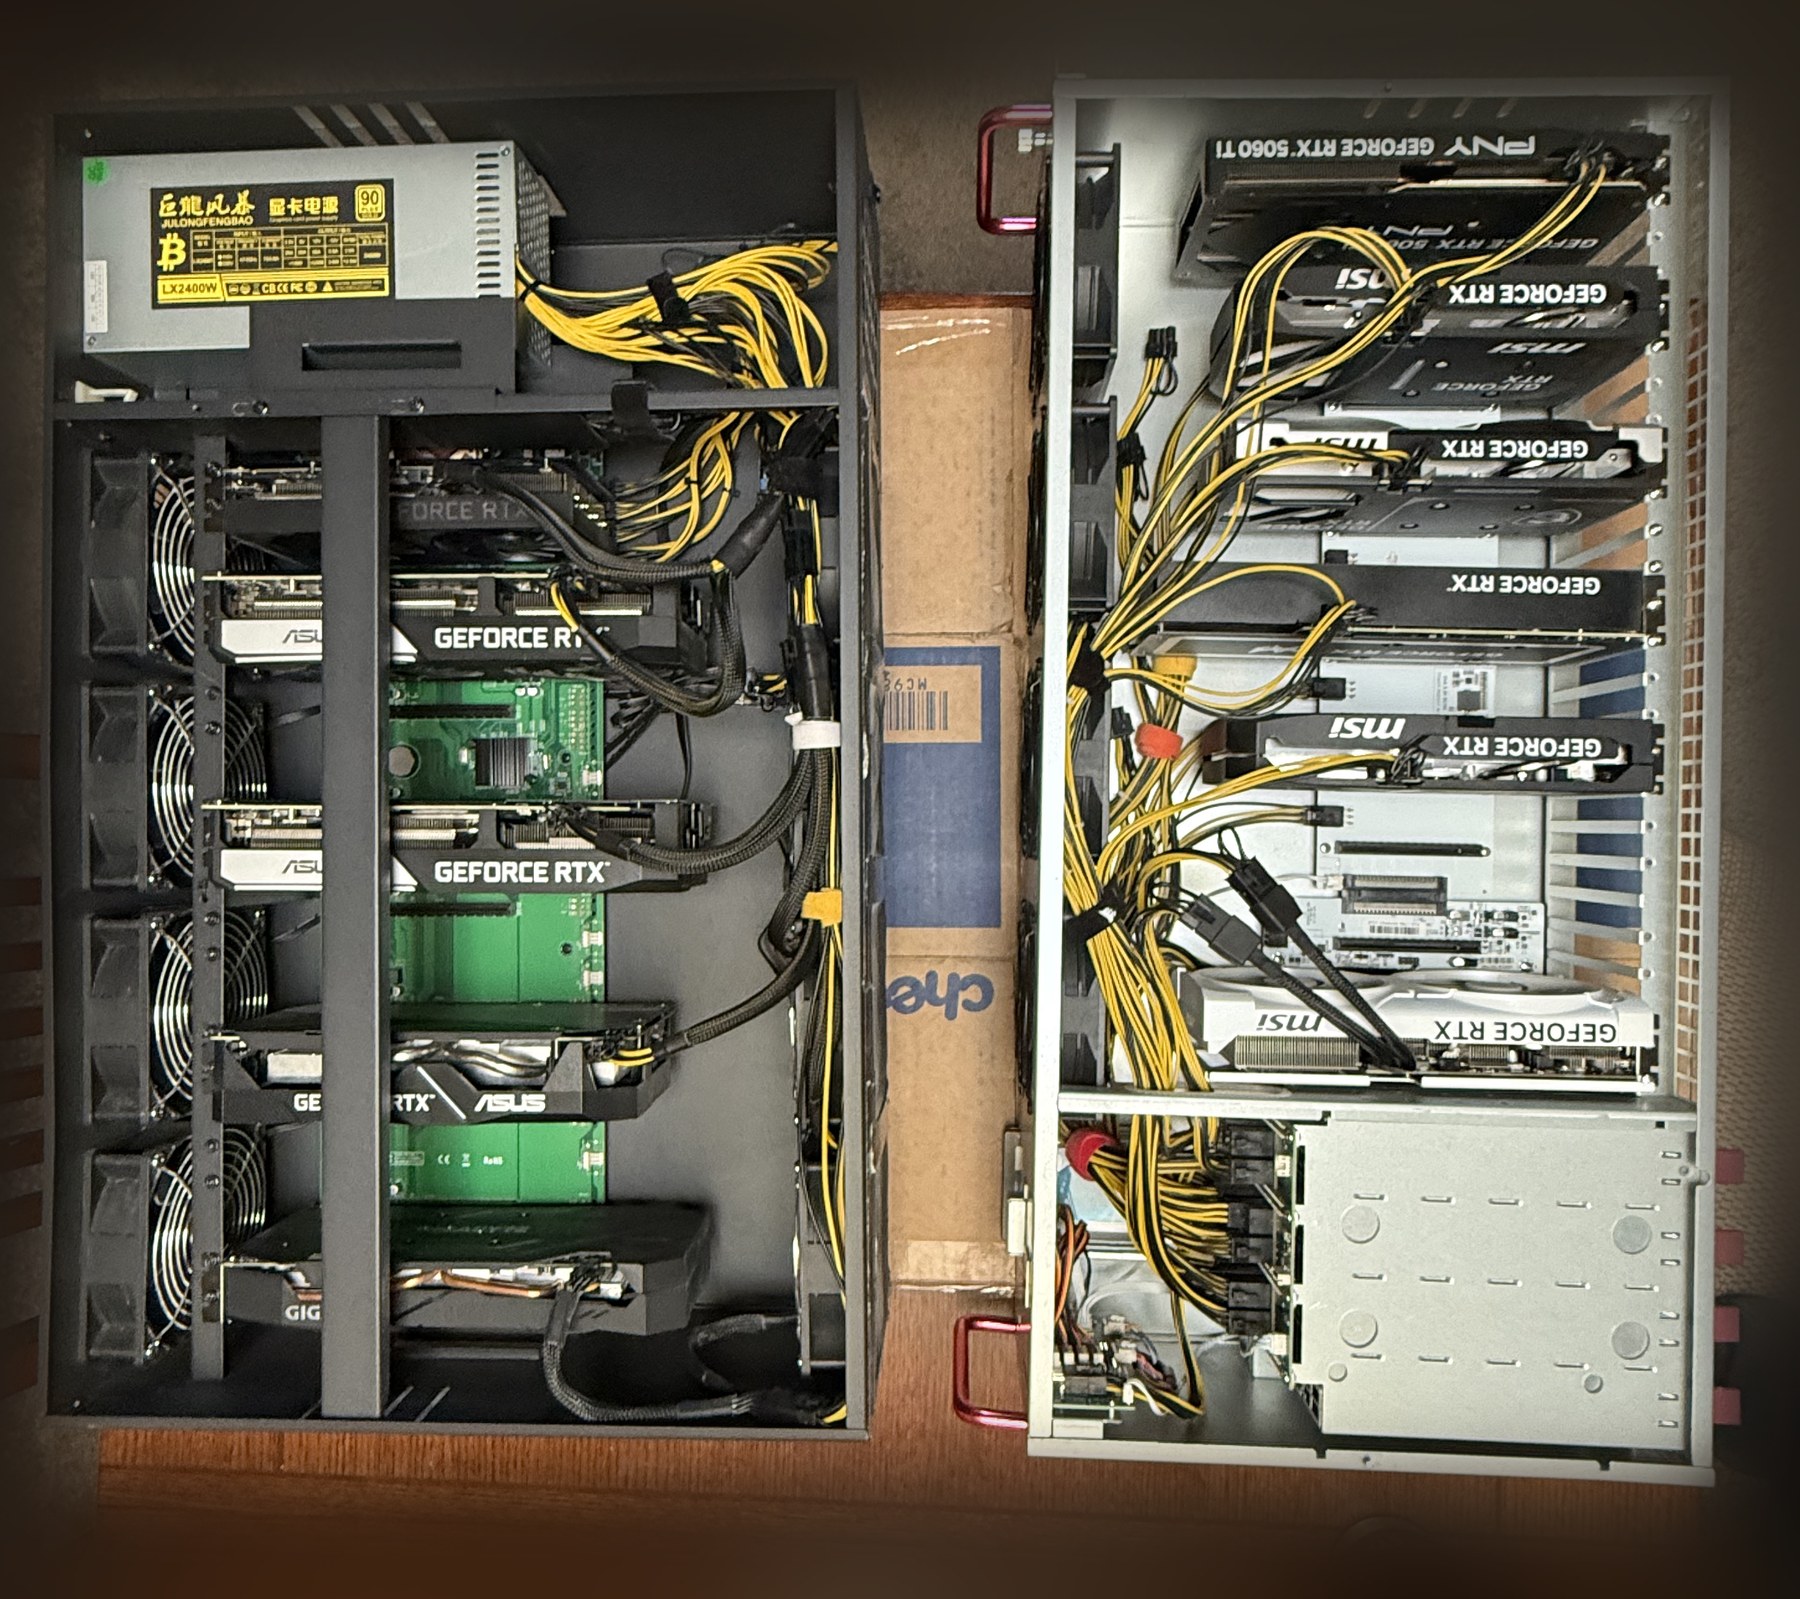 Era 13 • Oct 26
🔍 Embiggen
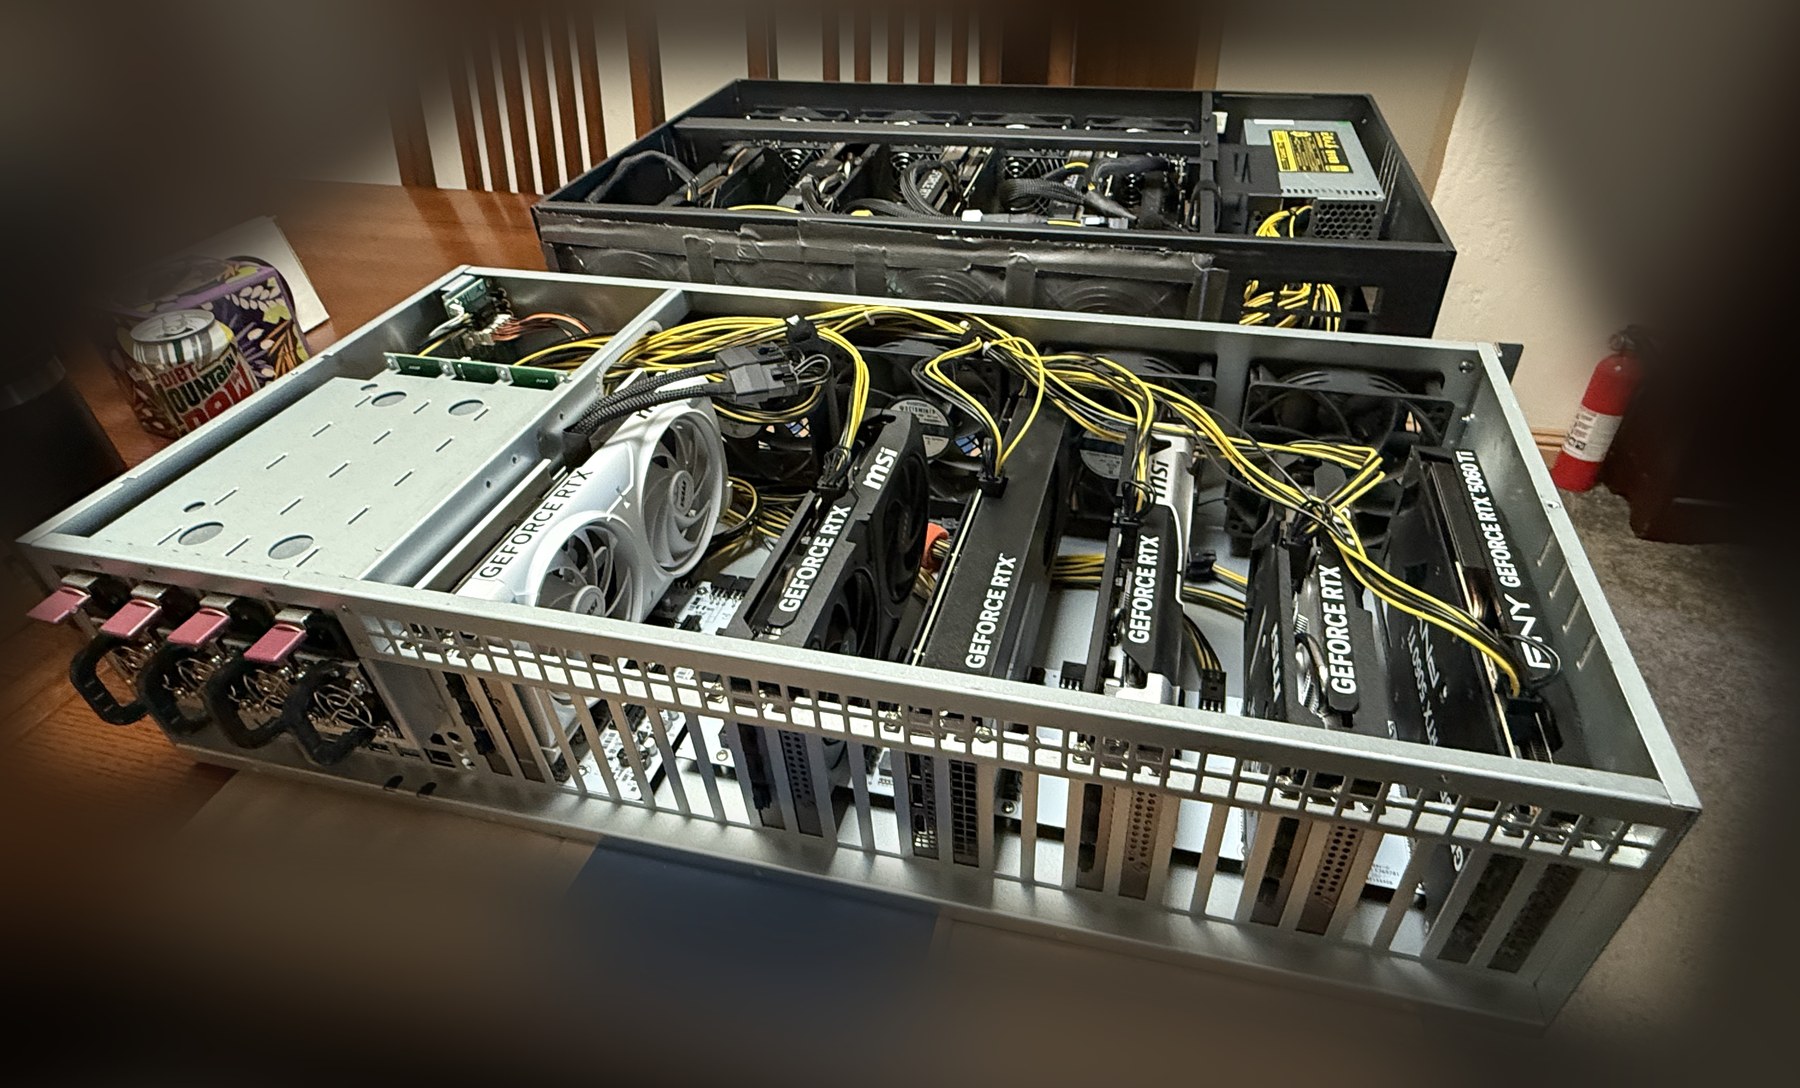 Era 13 • Oct 26
🔍 Embiggen
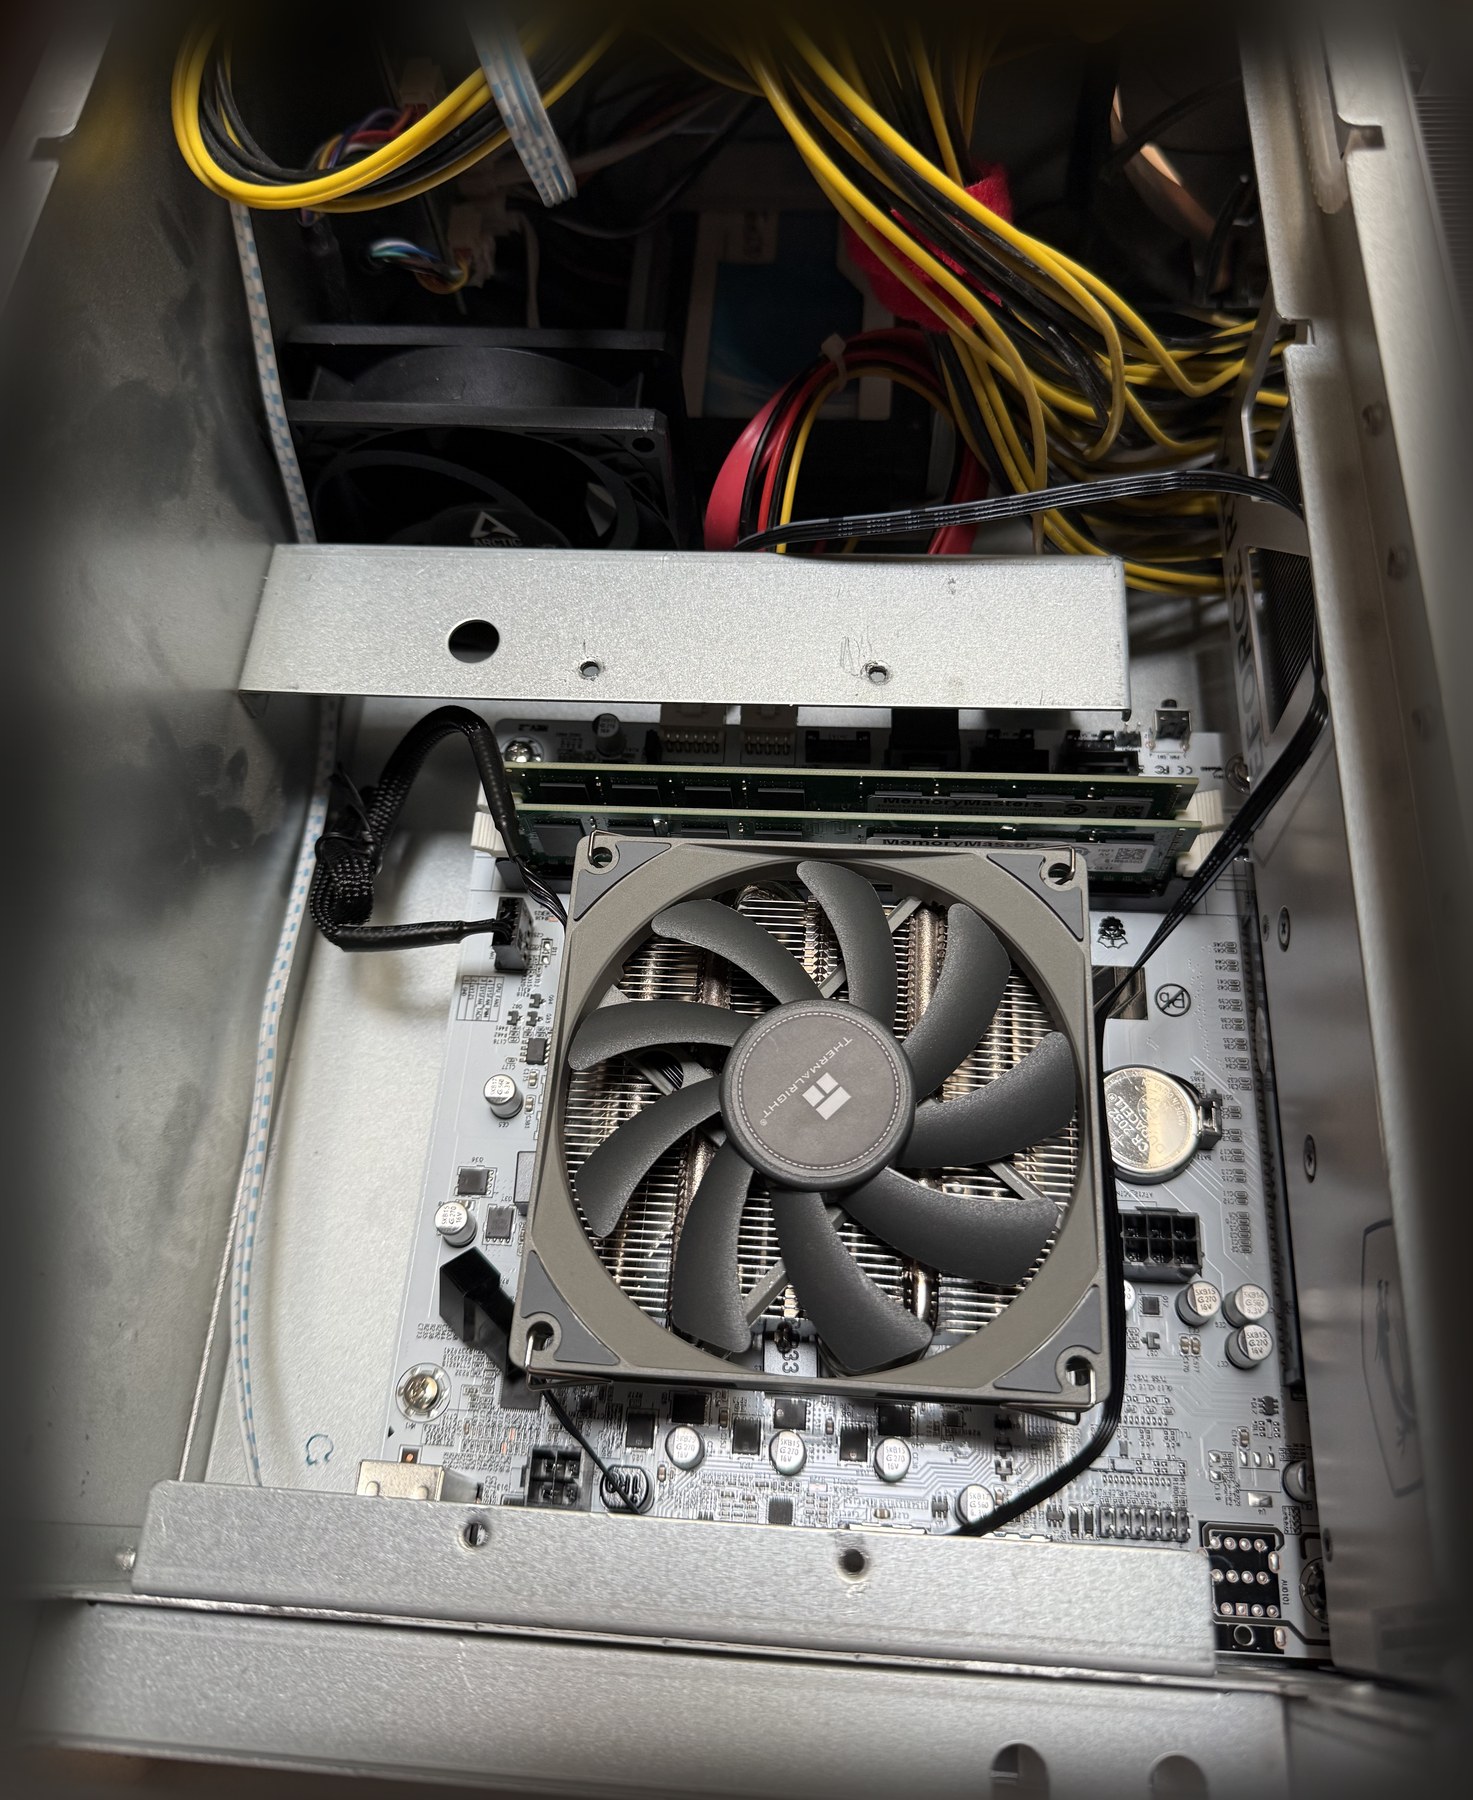 Era 13 • Oct 26+
🔍 Embiggen
 Era 13 • Oct 26+
🔍 Embiggen
🗺️ Physical to Logical GPU Ordering Map (Octominer X12 Ultra — scraps v2 5-GPU Array)
The physical slot designations are silk-screened on the Octominer X12 Ultra motherboard. Slot 1 is wired directly to the CPU as an unthrottled PCIe Gen 3.0 x16 link (housing the ZOTAC GeForce RTX 4070 Blower added November 1, 2026); Slots 2–12 are riserless physical x16 slots wired to the B250 PCH as PCIe Gen 3.0 x1 links (~985 MB/s per slot, housing the ZOTAC GeForce RTX 3070 in Slot 2 and the three RTX 3060 Ti cards in Slots 4, 7, and 10).
| OX12U Slot | Former Host / Slot | GPU Model | Host PCI Bus ID | NVIDIA Index | GPU UUID | Power Cap | Status & Notes |
|---|---|---|---|---|---|---|---|
| Slot 1 (Gen3 x16) | smallpieces v2 Slot 6 |
ZOTAC GeForce RTX 4070 Blower | 0000:01:00.0 |
0 |
d65f3411 |
160W (200W TGP) |
Active (12GB GDDR6X, CPU-direct Gen3 x16, 65% gpufanpin, raised from 145W Nov 10 ➔ 2,550 MHz) |
| Slot 2 (Gen3 x1) | OX12U Slot 1 | ZOTAC GeForce RTX 3070 | 0000:04:00.0 |
2 |
1522578d |
145W (220W TGP) |
Active (8GB GDDR6, PCH Gen3 x1, 65% gpufanpin, moved from Slot 1 Nov 1, 2026) |
| Slot 3 (Gen3 x1) | — | Empty | — | — | — | — | Empty (Airflow spacing) |
| Slot 4 (Gen3 x1) | GPNE Slot 1 | DELL GeForce RTX 3060 Ti | 0000:06:00.0 |
4 |
1ed25c7d |
140W (200W TGP) |
Active (8GB GDDR6, PCH Gen3 x1; raised from 125W Nov 10: 1,380 ➔ 1,635 MHz) |
| Slot 5 (Gen3 x1) | — | Empty | — | — | — | — | Empty (Airflow spacing) |
| Slot 6 (Gen3 x1) | — | Empty | — | — | — | — | Empty (Airflow spacing) |
| Slot 7 (Gen3 x1) | GPNE Slot 2 | ASUS GeForce RTX 3060 Ti | 0000:05:00.0 |
3 |
a76d84a0 |
140W (200W TGP) |
Active (8GB GDDR6, PCH Gen3 x1; raised from 125W Nov 10: 1,530 ➔ 1,650 MHz) |
| Slot 8 (Gen3 x1) | — | Empty | — | — | — | — | Empty (Airflow spacing) |
| Slot 9 (Gen3 x1) | — | Empty | — | — | — | — | Empty (Airflow spacing) |
| Slot 10 (Gen3 x1) | GPNE Slot 4 | ASUS GeForce RTX 3060 Ti | 0000:02:00.0 |
1 |
d1ea526f |
140W (200W TGP) |
Active (8GB GDDR6, PCH Gen3 x1; raised from 125W Nov 10: 1,575 ➔ 1,830 MHz) |
| Slot 11 (Gen3 x1) | — | Empty | — | — | — | — | Empty |
| Slot 12 (Gen3 x1) | — | Empty | — | — | — | — | Empty |
🐳 Container Runtime & Hardware Swap Procedure: See Fleet Docker Compose Architecture & Hardware Lifecycle for the standardized
/opt/docker-configs/fah-compose.yamlspecification,fah-start/fah-stoptimer lifecycle, and graceful GPU swap procedure shared across all fleet hosts.
🚀 Scraps v2 Upgrade: Octominer X12 Ultra Migration (Oct 26, 2026) & 5-GPU RTX 4070 Expansion (Nov 1, 2026)
Cutover Status — LIVE (Oct 26, 2026; Expanded to 5 GPUs Nov 1, 2026; QRB Power-Cap Tuned Nov 10, 2026):
scrapsv2 is live inside the Octominer X12 Ultra 12-slot server chassis at its original IP (.27), running its migrated mSATA/SATA storage volumes intact, closed-loopoctoctl v2.2.15fan control,gpufanpin v1.3.1(65%floor on bothGPU 0RTX 4070andGPU 2RTX 3070),nvpowerctl v1.3.4(160W, 140W, 145W, 140W, 140WGPU caps =725Wtotal [raised Nov 10 from665Wto lift the3x RTX 3060 Tioff theirV_minvoltage floor by+120..+255 MHzandRTX 4070to2,550 MHz] + MSR0x1a0unlock +3.00 GHzceiling +fah_main_cpus = 0, 3, 1, 2, 7), and its 5-GPU Ada/Ampere array (1x RTX 4070 + 1x RTX 3070 + 3x RTX 3060 Ti). Meanwhile,smallpiecesv3 (AMD Ryzen 9 9900X + PCIe Gen 5.0/4.0 x4 in the repurposed GPNE chassis) is live with its 5-GPU all-Blackwell array.
1. Executive Summary & Fleet Hardware Cascade
The legacy scraps v1 platform (Haswell Core i7-4790 on an AX-B85M-ETH board) was constrained by an immovable 8GB single-SODIMM DDR3 ceiling, PCIe 2.0 x1 slots, and a shared 120V / 15A circuit. Rather than purchasing a separate motherboard/CPU kit for scraps, the fleet executed a hardware cascade across smallpieces and scraps:
- Stage 1 (
scrapsv2 Migration into Octominer X12 Ultra — Completed Oct 26, 2026): Transplantedscraps's existing 128GB mSATA boot drive and 30GB 2.5" SATA/optdrive into the vacated Octominer X12 Ultra chassis (Core i7-7700 4C/8T, 32GB DDR3L RAM, Thermalright AXP90-X36 cooler, and 4x HPE 750W 240V Platinum Plus PSUs), enabledoctoctl.service, unlocked the B250 BIOS800 MHzlock vianvpowerctl v1.3.2, and initially deployed 4 Ampere GPUs (1x Zotac RTX 3070 in Slot 1 + 3x RTX 3060 Ti in Slots 4, 7, 10). - Stage 2 (
smallpiecesv3 All-Blackwell Cutover — Completed Oct 29, 2026): Rebuiltsmallpiecesv3 (Ryzen 9 9900X + ASUS TUF Gaming X670E-PLUS WiFi 6E + 32GB Kingston FURY DDR5-6000 + ADT-Link R34A Gen5 x4 bifurcation + 2400W PSU) inside the repurposed GPNE frame forsmallpieces's 5 Blackwell GPUs (1x RTX 5070 + 4x RTX 5060 Ti). - Stage 3 (
scrapsv2 5-GPU Expansion with ZOTAC RTX 4070 Blower — Completed Nov 1, 2026): Moved theZOTAC GeForce RTX 3070(1522578d,145W) from OX12U Slot 1 to OX12U Slot 2 (Gen3 x1, Bus04:00.0, GPU 2) and installed theZOTAC GeForce RTX 4070 Blower(d65f3411,12GB GDDR6X,145W) into CPU-direct OX12U Slot 1 (Gen3 x16, Bus01:00.0, GPU 0) alongside the threeRTX 3060 Ticards in Slots 4, 7, and 10.
2. Core Platform & GPU Lineup Comparison (scraps v1 ➔ scraps v2)
| Component Category | scraps v1 (Legacy GPNE / Haswell) |
scraps v2 (Octominer X12 Ultra / 5-GPU Ada+Ampere) |
Operational Benefit |
|---|---|---|---|
| Chassis & Cooling | GPNE 8-Fan Open/Closed Mining Frame | Octominer X12 Ultra 12-Slot Server Chassis (High-Static-Pressure Delta Fan Wall) | Closed-loop server telemetry (fan2 + OctoFan 0/2/4/6) and automated PWM + CPU thermal-assist fan control via octoctl v2.2.14. |
| Motherboard & CPU | AX-B85M-ETH + Intel Core i7-4790 (Haswell 4C/8T) | Octominer B250 Custom Board + Intel Core i7-7700 (Kaby Lake 4C/8T, MSR 0x1a0 unlocked) + Thermalright AXP90-X36 |
Upgrades Slot 1 to native PCIe Gen3 x16 and Slots 2–12 to native riserless PCIe Gen3 x1; configurable cpu_max_freq_khz ceiling balances TPF and CPU thermals. |
| System Memory (RAM) | 8GB DDR3-1600 SODIMM (1x 8GB max) | 32GB DDR3L-1600 SODIMM (2x 16GB, OPENMM_CPU_THREADS=4) |
4x RAM expansion eliminates kernel page-table lockups, OOM pressure, and zswap thrashing (0.00 KB/s swap). |
| Network Controller | Onboard Realtek PCIe Fast/Gigabit NIC | Onboard Realtek RTL8105E Fast Ethernet (100baseT/Full, 100 Mbps) |
Streams 67.3 MiB Project 15506 Work Units at ~11.2 MB/s wire speed (~8 seconds per WU download). |
| Power Infrastructure | 2400W PSU on shared 120V / 15A circuit | 4x HPE 750W Platinum Plus Server PSUs (3000W total capacity) | Direct riserless slot power via motherboard busbars plus high-efficiency Platinum PSU rails. |
| Storage Volumes | 128GB Transcend mSATA (/, ubuntu-vg) + 30GB SATA SSD (/opt, ubuntu-opt) |
Migrated intact from scraps v1 (LVM UUID mounts preserved) |
Zero-reinstall OS transition; preserves host SSH identity, F@H client state, and historical telemetry logs. |
| GPU Complement | 3x RTX 3060 Ti + 1x RTX 2060 SUPER + 1x RTX 2060 (5 GPUs: 3 Ampere, 2 Turing) | 1x ZOTAC RTX 4070 (Slot 1 x16, 145W) + 1x ZOTAC RTX 3070 (Slot 2 x1, 145W) + 3x RTX 3060 Ti (Slots 4, 7, 10 x1, 125W) | Replaces aging Turing 20-series cards with RTX 4070 (Ada) + RTX 3070 (Ampere) alongside 3x RTX 3060 Ti (5 GPUs, 665W total power cap). |
📊 Live Per-GPU Benchmarks: scraps v1 vs. scraps v2 (4-GPU & 5-GPU Regimes)
Shortly after initial cutover on October 26, 2026, all four Ampere GPUs in scraps v2 drew concurrent Project 15506 (FahCore_28 v0.1.3, 166,465 atoms) Work Units from Temple University's assignment server (vav17.fah.temple.edu), enabling a direct apples-to-apples comparison against historical Project 15506 runs on the exact same physical RTX 3060 Ti silicon inside scraps v1 (i7-4790 + PCIe Gen 2 x1). Following the November 1, 2026 expansion to 5 GPUs (adding the ZOTAC GeForce RTX 4070 Blower into CPU-direct Slot 1 Gen3 x16 and moving the ZOTAC GeForce RTX 3070 to Slot 2 PCH Gen3 x1 under 3.00 GHz + nvpowerctl v1.3.4 thread affinity), we measured the full 5-GPU lineup across Project 15506 (FahCore_28) and Project 18249 (FahCore_27):
| Host & Regime | GPU Model & Slot | Power Cap | CPU Clock & Power | Median TPF | Estimated PPD | PPD / Watt (GPU) | vs. scraps v1 3060 Ti |
|---|---|---|---|---|---|---|---|
scraps v1 (i7-4790, Gen2 x1) |
ASUS RTX 3060 Ti (d1ea526f) |
125W |
3.6–4.0 GHz (60.4W) |
59.47s (P15506, n=9) |
~2.83M PPD |
~22.6k PPD/W |
Baseline (1.00x) |
scraps v2 (BIOS Default 8x) |
3x RTX 3060 Ti (Slots 4, 7, 10) | 125W |
800 MHz (4.3W) |
59.0s – 61.0s (P15506) |
~2.76M – 2.86M PPD |
~22.4k PPD/W |
~0% (CPU-bottlenecked at 800 MHz) |
scraps v2 (4-GPU 24x Sweet Spot) |
3x RTX 3060 Ti (Slots 4, 7, 10) | 125W |
2.40 GHz (10.4W) |
55.0s – 56.0s (P15506) |
~3.14M – 3.31M PPD |
~25.1k – 26.5k PPD/W |
+11.0% to +17.0% PPD |
scraps v2 (Active 5-GPU 30x Sweet Spot) |
3x RTX 3060 Ti (Slots 4, 7, 10, Gen3 x1) | 125W |
3.00 GHz (18.5W) |
54.8s (P15506) / 60.2s (P18249) |
~3.29M – 3.52M PPD |
~26.3k – 28.2k PPD/W |
+16.3% to +24.4% PPD |
scraps v2 (4-GPU 24x Sweet Spot) |
Zotac RTX 3070 (Slot 1, Gen3 x16) | 145W |
2.40 GHz (10.4W) |
43.52s – 44.0s (P15506) |
~4.50M – 4.69M PPD |
~31.0k – 32.3k PPD/W |
+59.0% to +65.7% PPD (on Slot 1 x16) |
scraps v2 (Active 5-GPU 30x Sweet Spot) |
Zotac RTX 3070 (Slot 2, PCH Gen3 x1) | 145W |
3.00 GHz (18.5W) |
46.5s (P15506) |
~4.10M PPD |
~28.3k PPD/W |
+44.9% PPD (-12.5% vs Slot 1 x16 due to x1 link) |
scraps v2 (Active 5-GPU 30x Sweet Spot) |
ZOTAC RTX 4070 Blower (Slot 1, Gen3 x16) | 145W |
3.00 GHz (18.5W) |
39.0s (P18249) |
~6.05M – 6.62M PPD |
~41.7k – 45.6k PPD/W |
+113.8% to +133.9% PPD (for +16% power) |
Ref: smallpieces v2 (Blackwell) |
RTX 5060 Ti (PCH Gen3 x1) | 130W |
800 MHz (5.0W) |
39.84s (P15506, n=37) |
~5.24M PPD |
~40.3k PPD/W |
+85.2% PPD |
- Why Slot 1 (
CPU-Direct Gen3 x16) Belongs to theRTX 4070: Moving theZOTAC RTX 3070from Slot 1 (Gen3 x16) to Slot 2 (PCH Gen3 x1) cost+2.5–3.0sTPF onProject 15506(43.52s ➔ 46.5s, or-0.59M PPD), but freed CPU-direct Slot 1 (15.8 GB/s) for theZOTAC RTX 4070 Blower(d65f3411), which bursts up to2,997.64 MB/sTX /1,132.39 MB/sRX onProject 18249and adds+6.05M–6.62M PPD(41.7k–45.6k PPD/W) at the same145Wcap—yielding a net node gain of+6.50M PPD(13.70M ➔ 20.20M PPD). - 5-GPU Node Production Summary (
20.20M PPD@647.3W): At the3.00 GHz(0.980V,18.5W) 5-GPU operating point withnvpowerctl v1.3.4thread affinity (fah_main_cpus = 0, 3, 1, 2, 7),scrapsv2 sustains20.20M PPD(6.05M–6.62M + 4.10M + 3 × ~3.30M–3.52M) at628.8Wcombined GPU power and18.5WCPU package power (647.3Wtotal silicon draw =31.20k PPD/Watt).
Whole-Node Production & Silicon Efficiency: scraps v2 (4-GPU & 5-GPU Regimes) vs. scraps v1 Historical Telemetry (57,641 Samples)
Comparing 57,641 full-load 1-minute telemetry samples from scraps v1's historical neumon.log across both of its operational eras—Phase A (Jul 25 – Aug 28, 2026: 5 GPUs) and Phase B (Aug 29 – Oct 25, 2026: 3 GPUs + 2 idled Turings)—against both stages of scraps v2 (Oct 26–31 4-GPU Cutover and Nov 1+ 5-GPU Expansion) shows how replacing the Haswell/GPNE platform and Turing cards doubled output and efficiency at the exact same wall power:
| Node Metric | scraps v1 Phase A(5 GPUs: Jul 25 – Aug 28) |
scraps v1 Phase B(3 GPUs: Aug 29 – Oct 25) |
scraps v2 4-GPU(Oct 26 – Oct 31) |
scraps v2 5-GPU Live(Nov 1+ Expansion) |
v2 5-GPU vs. v1 5-GPU(Same GPU Count) |
|---|---|---|---|---|---|
| Active GPU Lineup | 5 GPUs: 3x 3060 Ti + 2060S + 2060 |
3 GPUs: 3x 3060 Ti (2 Turings idled) |
4 GPUs: 1x 3070 + 3x 3060 Ti |
5 GPUs: 1x 4070 + 1x 3070 + 3x 3060 Ti |
5 GPUs vs. 5 GPUs (Ada+Ampere vs. Ampere+Turing) |
| Host CPU, RAM & PCIe | i7-4790 (8GB DDR3, Gen2 x1) |
i7-4790 (8GB DDR3, Gen2 x1) |
i7-7700 @ 2.40 GHz (32GB, Gen3) |
i7-7700 @ 3.00 GHz (32GB, Gen3 x16/x1) |
Gen3 x16/x1 + 4x RAM + Thread Affinity |
| Full-Load Node PPD | 10.11M PPD(mean 10.39M, P90 12.44M) |
6.53M PPD(mean 6.51M, P90 7.10M) |
13.70M – 14.61M PPD |
20.20M PPD (20,197,060 PPD) |
+99.8% (2.00x PPD, +10.09M PPD) |
| Combined GPU Power Draw | 586.1 W (576.5W median) |
366.8 W (incl. 25W idle Turings) |
508.8 W |
628.8 W (665W cap) |
+42.7 W (+7.3%) |
| CPU Package Power Draw | 50.8 – 60.4 W (1.05V Haswell) |
50.8 W (1.03V Haswell) |
10.4 W (0.864V @ 2.40 GHz) |
18.5 W (0.980V @ 3.00 GHz) |
-32.3 W to -41.9 W (-63.6%) |
| Total Silicon Power (GPU + CPU) | 636.9 W |
417.6 W |
519.2 W |
647.3 W |
+10.4 W (+1.6%) |
| Whole-Node Efficiency (GPU + CPU) | 15.87k PPD/Watt |
15.64k PPD/Watt |
26.39k PPD/Watt |
31.20k PPD/Watt |
+96.6% (~2.0x PPD/Watt) |
| GPU & CPU Steady-State Temps | 66–77°C GPU / 74–82°C CPU |
58–66°C GPU / 68–74°C CPU |
55–61°C GPU / 55–60°C CPU |
55–63°C GPU / 66.0°C CPU |
-10°C to -14°C cooler GPUs & CPU |
- Doubling 5-GPU
scrapsv1 Output (10.11M➔20.20M PPD) for Just+10.4W(15.87k➔31.20k PPD/Watt): Replacing the two Turing 20-series cards (RTX 2060 SUPER + RTX 2060) with theZOTAC RTX 4070 Blower(145W) andZOTAC RTX 3070(145W) while dropping CPU package power from50.8–60.4W(i7-4790) to18.5W(i7-7700@3.00 GHz) delivers literally2.0xthe PPD (20.20Mvs.10.11M) at within1.6%(+10.4W) of the exact same total silicon power—lifting whole-node efficiency by+96.6%(31.20kvs.15.87k PPD/W) and tripling (3.09x) the6.53M PPDoutput of 3-GPUscrapsv1 Phase B. - 4-GPU Intermediate Baseline (Oct 26–31:
13.70M–14.61M PPD@519.2W): During its first five days with 4 Ampere GPUs (1x RTX 3070 + 3x RTX 3060 Tiat2.40 GHz/10.4WCPU),scrapsv2 sustained13.70M–14.61M PPD(43.52sRTX 3070TPF and54.58–55.51s3060 TiTPF onP15506) at26.39k PPD/W—already beating 5-GPUscrapsv1 by+35.5%while burning117.7Wless power.
How LAR.systems Rankings Work & Why scraps v2 Scores "Unicorn (+88%)" on P18264 vs "Normal" / "OK" on Un-Skewed Desktop Baselines
LAR.systems computes its slot performance badges (UNICORN >= +30%, GREAT +20..30%, GOOD +10..20%, NORMAL -10..+10%, OK -20..-10%, POOR -30..-20%, OOF < -30%) strictly per-(GPU Model, OS, Project ID) via model-specific JSON profiles (ad104_geforce_rtx_4070.json, ga104_geforce_rtx_3070.json, etc.). Because the LAR webclient periodically pushes active slot samples from open browser tabs, comparing the ZOTAC RTX 4070 Blower (d65f3411, 145W cap) across its first two Alzheimer's projects (919,221 atoms) on scraps v2 reveals two distinct phenomena:
- Self-Referential
"Unicorn (+88%)"onProject 18264(6.21M PPDvs LAR's3.31M PPDLinux Average across1,112samples): Nearly all1,112LinuxP18264samples in LAR'sad104_geforce_rtx_4070.jsondatabase were submitted by this exactRTX 4070during thesmallpiecesv2 era—when it was choked at~3.3M PPDon aPCIe Gen 3.0 x1riser (Slot 6) with thei7-7700BIOS-locked at800 MHz(MSR 0x1a0bit 38). Moving the card intoscrapsv2 Slot 1 (PCIe Gen 3.0 x16) with thei7-7700unlocked to3.00 GHzandTID == PIDthread affinity isolated lifted itsP18264speed by+88.0%(3.31M➔6.21M PPD), earning a live"UNICORN"badge against its own historical baseline! "Normal"/"OK"(-6%to-14%) on Un-Skewed Desktop Baselines (P18258,P15506): On projects where LAR's Linux average was set by un-capped200–220Wsingle-GPU desktop PCs on modern DDR4/DDR5 CPUs—such asP18258on theRTX 4070(~6.88M PPDvs LAR's8.00M PPDaverage acrossn=15samples =-14.0%"OK") orP15506on theRTX 3070(~4.10M PPDvs LAR's4.36M PPDaverage =-6.0%"NORMAL")—five architectural differences betweensmallpiecesv3 (Ryzen 9 9900X) andscrapsv2 (i7-7700Octominer) govern the gap:
| Bottleneck Dimension | smallpieces v3 ("Unicorn" Tier) |
scraps v2 ("Normal" / "OK" on Un-Skewed Projects; "Unicorn" vs sp v2 on P18264) |
Measured Impact on *070 GPUs |
|---|---|---|---|
| 1. PCIe Lane Width & Topology | 4x PCIe Gen 5.0 x4 (15.8 GB/s) + 1x Gen 4.0 x4 (7.9 GB/s), all wired directly to the CPU (0 PCH contention). |
RTX 4070 on Slot 1 Gen 3.0 x16 (15.8 GB/s), but RTX 3070 on Slot 2 Gen 3.0 x1 (~0.98 GB/s) multiplexed through the B250 PCH alongside 3x 3060 Ti. |
Moving the RTX 4070 from sp v2 Slot 6 (Gen3 x1 + 800 MHz CPU) to scraps Slot 1 (Gen3 x16 + 3.0 GHz CPU) lifted its P18264 output +88% (3.31M ➔ 6.21M PPD); moving the RTX 3070 from Slot 1 (x16) to Slot 2 (x1) slowed P15506 TPF from 43.5s (4.69M) ➔ 46.5s (4.10M, -12.5%). |
| 2. Physical CPU Cores per GPU | 12 Zen 5 cores / 24 threads (4.7–5.2 GHz) for 5 GPUs (2.4 physical cores per GPU). OpenMM's 4 barrier threads per GPU run on idle physical cores without ever touching a CUDA polling core. |
4 Kaby Lake cores / 8 threads (3.00 GHz) for 5 GPUs (0.8 physical cores per GPU). 5 GPUs > 4 physical cores: every physical core's execution units are shared across CUDA polling + 20 OpenMM helper threads (5 × 4). |
Even with TID == PID pinned so main CUDA threads never collide, OpenMM's host-side PME/barostat reductions and 1% JSON frame writes run ~2.5x slower per step than on Zen 5. |
| 3. L3 Cache & RAM Bandwidth | 64 MB L3 Cache + Dual-Channel DDR5-6000 (~75 GB/s). OpenMM host force arrays fit inside L3 cache; checkpoints compress in <1.2s. |
8 MB L3 Cache (1/8th) + DDR3L-1600 (~21 GB/s, 1/3.5th). Host-side atom coordinate arrays spill to DDR3L RAM; 5% checkpoints stall GPU 0 (RTX 4070) for 5.0–6.0s (0% SM%). |
On Project 18249, the RTX 4070 completes 1% steps in 37s, but loses 5–6s every 5% checkpoint (39.0s effective TPF = ~6.05M PPD). |
| 4. CUDA Driver Polling Model | Blackwell (RTX 5070 / 5060 Ti) uses cudaDeviceScheduleYield / event-driven waits (~71% host CPU load for 5 GPUs), leaving idle CPU headroom for OpenMM steps. |
Ada (RTX 4070) uses aggressive cuEventSynchronize spin-polling (100% RNl core lock), saturating a full logical core continuously. |
Requires nvpowerctl v1.3.4 thread affinity isolation (fah_main_cpus = 0, 3, 1, 2, 7) so the RTX 4070's spin loop never time-slices another GPU's main loop. |
| 5. TSMC Node V/F Curve under Power Cap | Blackwell (TSMC 4NP) at 165W (5070) / 130W (5060 Ti) holds 2,700–2,850 MHz (95–98% of stock clock), beating stock-TGP LAR averages submitted on older CPUs. |
Ampere (Samsung 8nm 3070) at 145W (-34% vs 220W TGP) drops from ~1,950 MHz to 1,695 MHz (-13% clock); Ada (4070) at 145W (-28% vs 200W) runs at 2,445 MHz vs ~2,750 MHz stock. |
On un-skewed projects (P18258, P15506), LAR.systems' "Unicorn" threshold for 3070 / 4070 is set by 200–240W desktop cards on PCIe x16 + DDR4/DDR5, whereas scraps trades top-end clock for 31.2k PPD/W efficiency. |
🌡️ Kaby Lake i7-7700 Multiplier, Vcore & Thermal Sweet-Spot Analysis (2.40 GHz 4-GPU & 3.00 GHz 5-GPU Regimes)
When all GPUs initially began folding with MSR 0x1a0 bit 38 cleared and scaling_max_freq uncapped, two hardware behaviors of the Octominer B250 mining motherboard and Thermalright AXP90-X36 1U cooler surfaced:
- Why
smallpiecesv2 Ran So Cool in the Same Chassis (50–56°C): Auditing15,720historicalneumon.logsamples fromsmallpiecesv2 revealed that because the Octominer B250 BIOS boots withIA32_MISC_ENABLE(MSR 0x1a0) bit 38 set (0x4000850089),intel_pstatewas locked into its minimum8x(800 MHz) LFM state 93.1% of the time. At800 MHz, thei7-7700requests only0.672 VVcore and draws just4.3–5.7 Wpackage power—allowing the CPU to sit at50–56°Ceven with the Octominer chassis fans idling at22%(1,805 RPM). - Hard B250 BIOS Multiplier Ceiling at
36x(3.60 GHz) & Quadratic Vcore Heating: Even after clearing bit 38 ofMSR 0x1a0(0x850089), the Octominer B250 mining BIOS programsMSR_CONFIG_TDP_NOMINAL(0x648 = 0x24) andMSR_PERF_STATUS(0x198 = 0x2400) to cap the physical hardware multiplier at36x(3.60 GHzbase clock) regardless ofMSR_TURBO_RATIO_LIMIT(0x1ad = 0x2829292a). Because eachFahCoreprocess busy-pollscuEventSynchronizecontinuously on one CPU thread, running 4–5 active GPU workers at36x(3.60 GHz) drives Vcore to1.14 Vand CPU package power to25.3–28.0 W(6xhigher heat dissipation than800 MHz), pushing the low-profile 36mm CPU cooler to83–89°Cunless the loud Delta chassis fans ramp to85%(4,700 RPM).
Live Multiplier, Vcore, Package Power & TPF Sweep (4-GPU & 5-GPU Load)
By sweeping /sys/devices/system/cpu/cpufreq/policy*/scaling_max_freq across every Kaby Lake P-state multiplier under live 4-GPU and 5-GPU load, we mapped the non-linear V/F curve of the i7-7700 inside the Octominer X12 Ultra:
| CPU Multiplier & Clock | scaling_max_freq |
VID / Vcore (MSR 0x198) |
CPU Package Power (RAPL) | CPU Temp | RTX 3070 TPF (P15506) |
3x RTX 3060 Ti TPF (P15506) |
Acoustic & Thermal Assessment |
|---|---|---|---|---|---|---|---|
8x (800 MHz) (BIOS Default) |
800000 |
0.672 V (672 mV) |
4.3 W |
51–57°C |
48.0–50.0s |
59.0–61.0s |
Whisper-quiet (1,805 RPM), but starves OpenMM frame dispatch (+4–5s TPF penalty). |
16x (1.60 GHz) |
1600000 |
0.744 V (744 mV) |
5.9 W |
58°C |
~45.8s |
~57.4s |
Whisper-quiet; recovers ~60% of clock-scaling TPF gain for only +1.6W. |
20x (2.00 GHz) |
2000000 |
0.800 V (800 mV) |
8.2 W |
59°C |
~44.7s |
~56.5s |
Whisper-quiet; sub-10W CPU package power. |
24x (2.40 GHz) (4-GPU Sweet Spot) |
2400000 |
0.864 V (864 mV) |
10.4 W |
58–60°C |
44.0s (Slot 1 x16) |
56.0s |
4-GPU Sweet Spot: Cuts CPU power by -59% vs. 3.6 GHz when 4 GPUs = 4 physical cores. |
28x (2.80 GHz) |
2800000 |
0.944 V (944 mV) |
14.0 W |
64°C |
~43.4s |
~55.3s |
Vcore crosses 0.94V; intermediate step for 4 GPUs. |
30x (3.00 GHz) ⭐ |
3000000 |
0.980 V (980 mV) |
18.5 W |
65–66°C |
46.5s (Slot 2 x1) |
54.8s |
Active 5-GPU Sweet Spot (performance governor + fah_thread_affinity): Keeps Vcore below 1.0V and CPU temp 9°C below 75°C fan-assist threshold while feeding 5 GPUs (incl. RTX 4070 at 39.0s on P18249) across 4 physical cores. |
32x (3.20 GHz) |
3200000 |
1.040 V (1,040 mV) |
20.5 W |
69–71°C |
~42.9s |
~54.8s |
Vcore crosses 1.0V; thermal margin tightens on 36mm cooler. |
34x (3.40 GHz) |
3400000 |
1.080 V (1,080 mV) |
23.2 W |
72–74°C |
~42.7s |
~54.5s |
Approaching CPU thermal assist threshold (75°C). |
36x (3.60 GHz) (B250 Max) |
3600000 |
1.140 V (1,140 mV) |
25.3–28.0 W |
83–89°C (75°C @ 85% fans) |
42.54s |
54.33s |
Requires loud 4,700 RPM chassis fans to cool 25–28W for only ~0.5–1.5s faster TPF. |
Production Daemon Configuration (nvpowerctl v1.3.4 + gpufanpin v1.3.1 + octoctl v2.2.15)
nvpowerctl v1.3.4(/opt/etc/nvpowerctl.conf): With the November 1, 2026 expansion to 5 GPUs (20.20M PPD@665Wcap baseline) and the November 10, 2026 whole-system QRB power-cap recalibration to725Wtotal GPU cap (gpu_0 = 160,gpu_1 = 140,gpu_2 = 145,gpu_3 = 140,gpu_4 = 140— un-starving the threeRTX 3060 Ticards from1,380–1,575 MHzto1,635–1,830 MHzand lifting theRTX 4070from2,445 ➔ 2,550 MHz),nvpowerctl v1.3.4enforcescpu_turbo = enabled,cpu_scaling_governor = performance,cpu_max_freq_khz = 3000000(3.00 GHzat~0.98V/~18.5W/~66°CCPU package temp—keeping thei7-77009°Cbelowoctoctl's75°Cchassis fan ramp threshold while preventing idle logical cores from dropping to800 MHzbetween OpenMM barrier wakes), andfah_thread_affinity = enabled(fah_main_cpus = 0, 3, 1, 2, 7):- How
nvpowerctlEnforces CPU Affinity Under the Hood (apply_fah_thread_affinity): EachFahCoreprocess spawns 28 threads in/proc/<pid>/task/<tid>: 1 main CUDA dispatch thread (TID == PID) that busy-pollscuEventSynchronize/ioctlat~98–100%CPU (RNl), plus 27 helper threads (TID != PID) including 4 OpenMM CPU barrier threads (OPENMM_CPU_THREADS=4). On startup and every15swatchdog poll,nvpowerctlscans/proc/[0-9]*/commforFahCore*, extracts the GPU index from-gpu <idx>in/proc/<pid>/cmdline, and checksos.sched_getaffinity(pid)(idempotent—zero syscalls or log noise once pinned). Whenever a new Work Unit spawns a freshFahCorePID,nvpowerctliterates/proc/<pid>/task/*and calls Linuxsched_setaffinity(2)directly via Python:- Main CUDA Loop (
tid == pid) ➔ Dedicated Single Logical Core ({target_cpu}): PinsGPU 0(RTX 4070) tocpu0(Core 0 primary),GPU 2(RTX 3070) tocpu1(Core 1 primary),GPU 3(RTX 3060 Ti) tocpu2(Core 2 primary), andGPU 1 & GPU 4(2x RTX 3060 Ti) tocpu3 & cpu7(Core 3's two hardware SMT threads)—guaranteeing two100%-spinning main CUDA loops never land on the same logical core and time-slice each other50%/50%. - OpenMM Helper Threads (
tid != pid) ➔ All Logical Cores ({0..7}): Keeps all 8 logical cores open for the 4 OpenMM barrier threads so step-boundary reductions execute in parallel across the unshared SMT siblings (cpu4, cpu5, cpu6) without serializing on a single core.
- Main CUDA Loop (
- How
gpufanpin v1.3.1(/opt/etc/gpufanpin.conf): Pins both theZOTAC GeForce RTX 4070 Blower(GPU 0, OX12U Slot 1) and theZOTAC GeForce RTX 3070(GPU 2, OX12U Slot 2;gpu_index = 0, 2,target_fan_speed = 65) to65%via direct headlesslibnvidia-ml.so.1C-libraryctypes(nvmlDeviceSetFanSpeed_v2/nvmlDeviceSetDefaultFanSpeed_v2over/dev/nvidiactl, zero Xorg/Coolbits) during active folding, holding theRTX 4070at64–66°Cat160Wcap and dropping theRTX 3070median core temp from60.0°C ➔ 52.0°C(-8.0°C,-0.9Wleakage,-60%transientGA104hotspot blips).octoctl v2.2.15(/opt/etc/octoctl.conf):- Direct Super I/O CPU Cooler Fan Curve (
nct6779pwm2): Because the Nuvotonnct6795DSuper I/O chip's autonomous SmartFan IV curve reads a sluggish PECI sensor (~15–20°Cbelow true IntelcoretempPackage ID 0),octoctlmanagespwm2directly using realcoretemppackage temperatures, ramping the Thermalright AXP90-X36 fan smoothly to100%(~2,740 RPM) whenever the CPU reaches65°C. - Secondary CPU Thermal Assist on Chassis Fan Wall (
CPU_TEMP_START=75,CPU_TEMP_MAX=90): The 4 high-static-pressure Octominer Delta chassis fans stay on their quiet GPU curve (1,805–2,700 RPMwhen GPUs are55–67°C) during3.00 GHzoperation (66°CCPU), and only ramp to assist the CPU cooler if CPU package temperature ever exceeds75°C.
- Direct Super I/O CPU Cooler Fan Curve (
🔬 baseliner v3.7.1 Multi-GPU Scaling & Cycle Decomposition (0-GPU ➔ 1-GPU ➔ 2-GPU ➔ 4-GPU ➔ 5-GPU)
Using baseliner v3.7.1 (baseliner --compare), we captured 30-second high-frequency (250ms PCIe / NVML polling + hardware PMU cycle counters) baselines across all five operational load stages on scraps v2:
- 0-GPU Idle Baseline (
scraps_baseline_20261026_172421.log): All GPUs idle (P8state,34.5Wtotal GPU power, CPU idling at800 MHz). - 1-GPU Folding Baseline (
scraps_baseline_20261026_175735.log): Slot 1Zotac RTX 3070foldingP15506(WU1823) solo at3.60 GHzCPU clock. - 2-GPU Folding Baseline (
scraps_baseline_20261026_182358.log): Slot 1RTX 3070+ Slot 7ASUS RTX 3060 Ti(WU1825) folding concurrently at3.60 GHzCPU clock. - 4-GPU Full-Tilt Baseline @
2.40 GHz(scraps_baseline_20261026_184741.log): All 4 Ampere GPUs (1x RTX 3070 + 3x RTX 3060 Ti) foldingP15506concurrently at the2.40 GHz(0.864V,10.4W,powersavegovernor) 4-GPU sweet spot. - 5-GPU Full-Tilt Production Baseline @
3.00 GHz+ Thread Affinity (scraps_baseline_20261101_161610.log): All 5 Ada/Ampere GPUs (GPU 0: RTX 4070on Slot 1Gen3 x16+GPU 2: RTX 3070on Slot 2Gen3 x1+GPU 1, 3, 4: 3x RTX 3060 Tion Slots 10, 7, 4Gen3 x1) folding concurrently (20.20M PPD) at the3.00 GHz(0.980V,18.5W,performancegovernor +fah_main_cpus = 0, 3, 1, 2, 7) 5-GPU production sweet spot.
| Telemetry Metric (30s Window) | 0-GPU Idle | 1-GPU (3070) |
2-GPU (3070 + 3060 Ti) |
4-GPU @ 2.40 GHz |
5-GPU Full Tilt @ 3.00 GHz |
|---|---|---|---|---|---|
| CPU Clock, Governor & Power | 800 MHz (~3.8W) |
3,600 MHz (~11W) |
3,600 MHz (~16W) |
2,400 MHz powersave (10.4W) |
3,000 MHz performance (18.5W @ 0.980V) |
CPU Busy % (usr% / sys%) |
5.03% (1.5% / 3.1%) |
17.03% (12.0% / 4.7%) |
30.17% (21.4% / 8.4%) |
55.66% (36.6% / 18.6%) |
68.07% (62.8% / 5.3%) |
| CPU Idle % / IO Wait % | 94.97% / 0.00% |
82.97% / 0.00% |
69.83% / 0.00% |
44.34% / 0.00% |
31.93% / 0.00% |
| Total Unhalted CPU Cycles | 21.88 Gcyc |
136.32 Gcyc |
253.04 Gcyc |
321.31 Gcyc |
485.15 Gcyc |
| ↳ Time-Bound MMIO Wait Cycles | 5.56 Gcyc (25.4%) |
7.51 Gcyc (5.5%) |
14.00 Gcyc (5.5%) |
5.56 Gcyc (1.7%) |
9.36 Gcyc (1.9%) |
| ↳ True Compute / Kernel Cycles | 16.32 Gcyc (74.6%) |
128.81 Gcyc (94.5%) |
239.04 Gcyc (94.5%) |
301.55 Gcyc (93.8%) |
463.90 Gcyc (95.6%) |
| Hardware Interrupts / sec | 7,534.7 /s |
15,595.7 /s |
25,738.0 /s |
43,878.0 /s |
51,796.0 /s (~10.4k /s per GPU) |
Context Switches / sec (vmstat) |
3,412 /s |
3,310 /s |
3,245 /s |
3,181 /s |
2,949 /s (-7.3% via thread affinity) |
| Free System RAM / Swap Rate | 21,341 MB / 0.00 KB/s |
20,971 MB / 0.00 KB/s |
20,664 MB / 0.00 KB/s |
20,535 MB / 0.00 KB/s |
18,365 MB / 0.00 KB/s |
| Combined GPU Power Draw | 34.5 W |
174.1 W |
284.7 W |
508.8 W |
626.8 W (628.8W steady state) |
GPU SM Utilization (0/1/2/3[/4]) |
0% / 0% / 0% / 0% |
95.6% / 0% / 0% / 0% |
95.3% / 0% / 95.3% / 0% |
94.4% / 95.9% / 93.8% / 95.9% |
87.7% / 94.9% / 93.8% / 95.3% / 87.6%( 94–100% between 5% checkpoints) |
| Combined PCIe TX / RX Avg (Peak) | 0.0 / 0.0 MB/s |
34.9 / 26.8 MB/s (255 MB/s) |
68.8 / 52.8 MB/s (367 MB/s) |
122.6 / 91.9 MB/s (517 MB/s) |
438.9 / 303.6 MB/s( 2,998 MB/s TX / 1,132 MB/s RX Peak) |
Key Architectural Takeaways from the 5-Stage baseliner Progression
2,997.64 MB/s(3.00 GB/s) Peak PCIe Bursts Prove Why theRTX 4070Needed Slot 1 (Gen3 x16): High-frequency250msPCIe telemetry in the 5-GPU capture (scraps_baseline_20261101_161610.log) caughtGPU 0(ZOTAC RTX 4070 BlowerrunningFahCore_27Project 18249in Slot 1CPU-direct Gen3 x16) bursting to2,997.64 MB/sPeak TX and1,132.39 MB/sPeak RX (190.14 MB/savg TX /61.61 MB/savg RX)—3.0xthe physical985 MB/sceiling of a B250 PCHPCIe Gen 3.0 x1slot. Meanwhile, on the four PCHGen 3.0 x1slots,GPU 3(ASUS RTX 3060 TirunningFahCore_27P18249in Slot 7) peaked at908.57 MB/sTX /803.47 MB/sRX (92%of itsx1link limit), while the threeFahCore_28(P15506) cards (GPU 1, 2, 4) peaked at339–357 MB/sRX (35%ofx1link capacity).-71.5%Drop in Kernel%sysTime (18.6%➔5.3%) & Fewer Context Switches withnvpowerctl v1.3.4Thread Affinity: Even after adding a 5th GPU (raising hardware interrupts by+18.0%from43,878/sto51,796/s), moving from un-pinnedpowersave(2.40 GHz) to pinnedfah_thread_affinity = 0, 3, 1, 2, 7+performance(3.00 GHz) slashed kernel%sysCPU overhead from18.6%down to5.3%and reduced context switches by-7.3%(3,181/s ➔ 2,949/s), because isolating eachFahCoremain thread (TID == PID) onto its own logical core stops the Linux scheduler from migrating spinning CUDA loops across cores or time-slicing two main loops on the same runqueue.- Onboard
100 MbpsFast Ethernet & Work Server Sequential Downloads: The Octominer B250 (B8PLUS2.0) motherboard integrates a Realtek RTL8105E Fast Ethernet controller (100baseT/Full,~11.2 MB/smax TCP payload throughput). When multiple GPUs request new Work Units simultaneously in the same F@H resource group, the F@H v8.4.9 client downloads multi-megabyte assignment payloads sequentially one-by-one (~8 seconds per67.3 MiBP15506WU over the100 Mbpslink once the upstream assignment server begins streaming).
3. Cutover Execution Notes & Historical scraps v1 Slot Map
scraps v1.0 Glamour Shots (AX-B85M-ETH in GPNE Frame • Eras 9–12)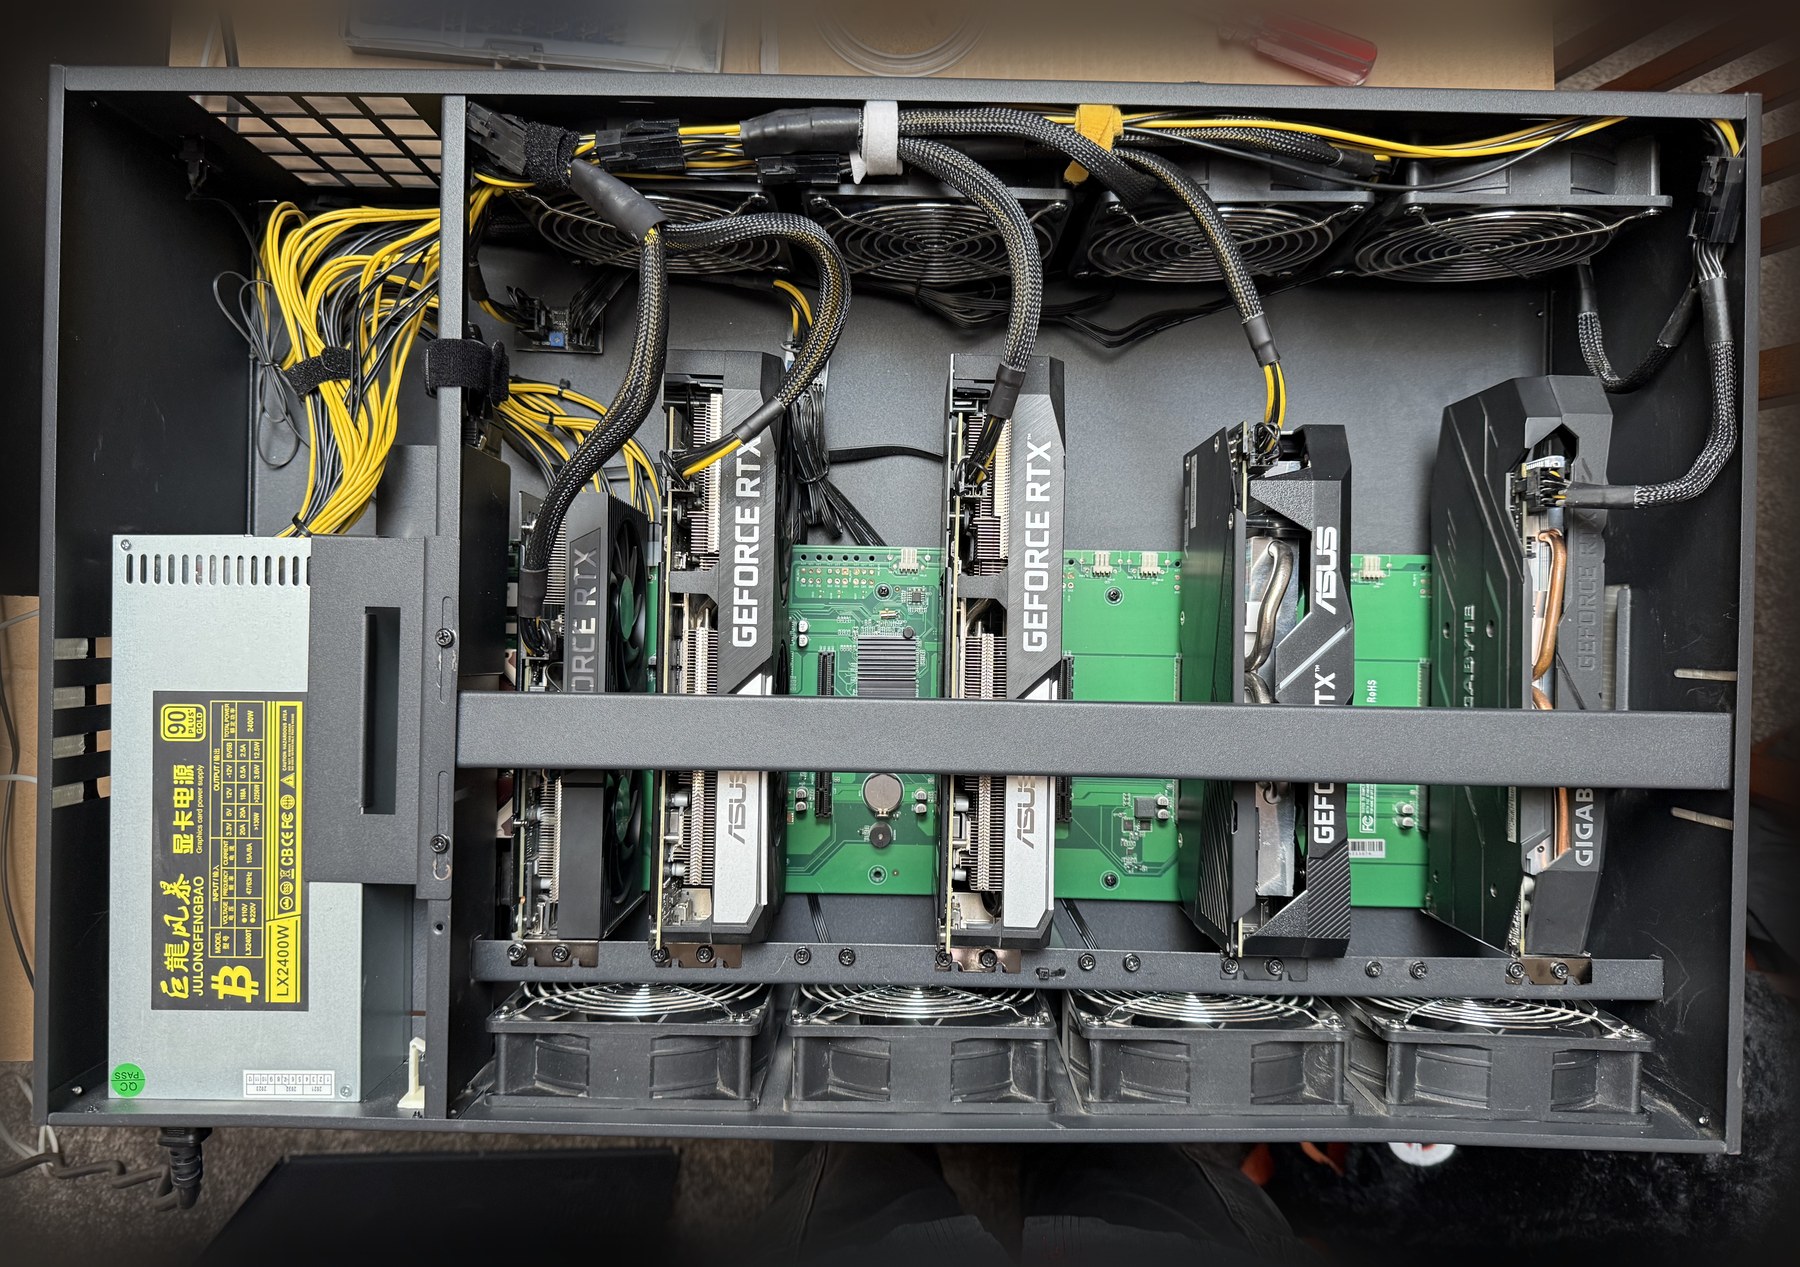 Era 9–10 • Jul 25–Aug 28
🔍 Embiggen
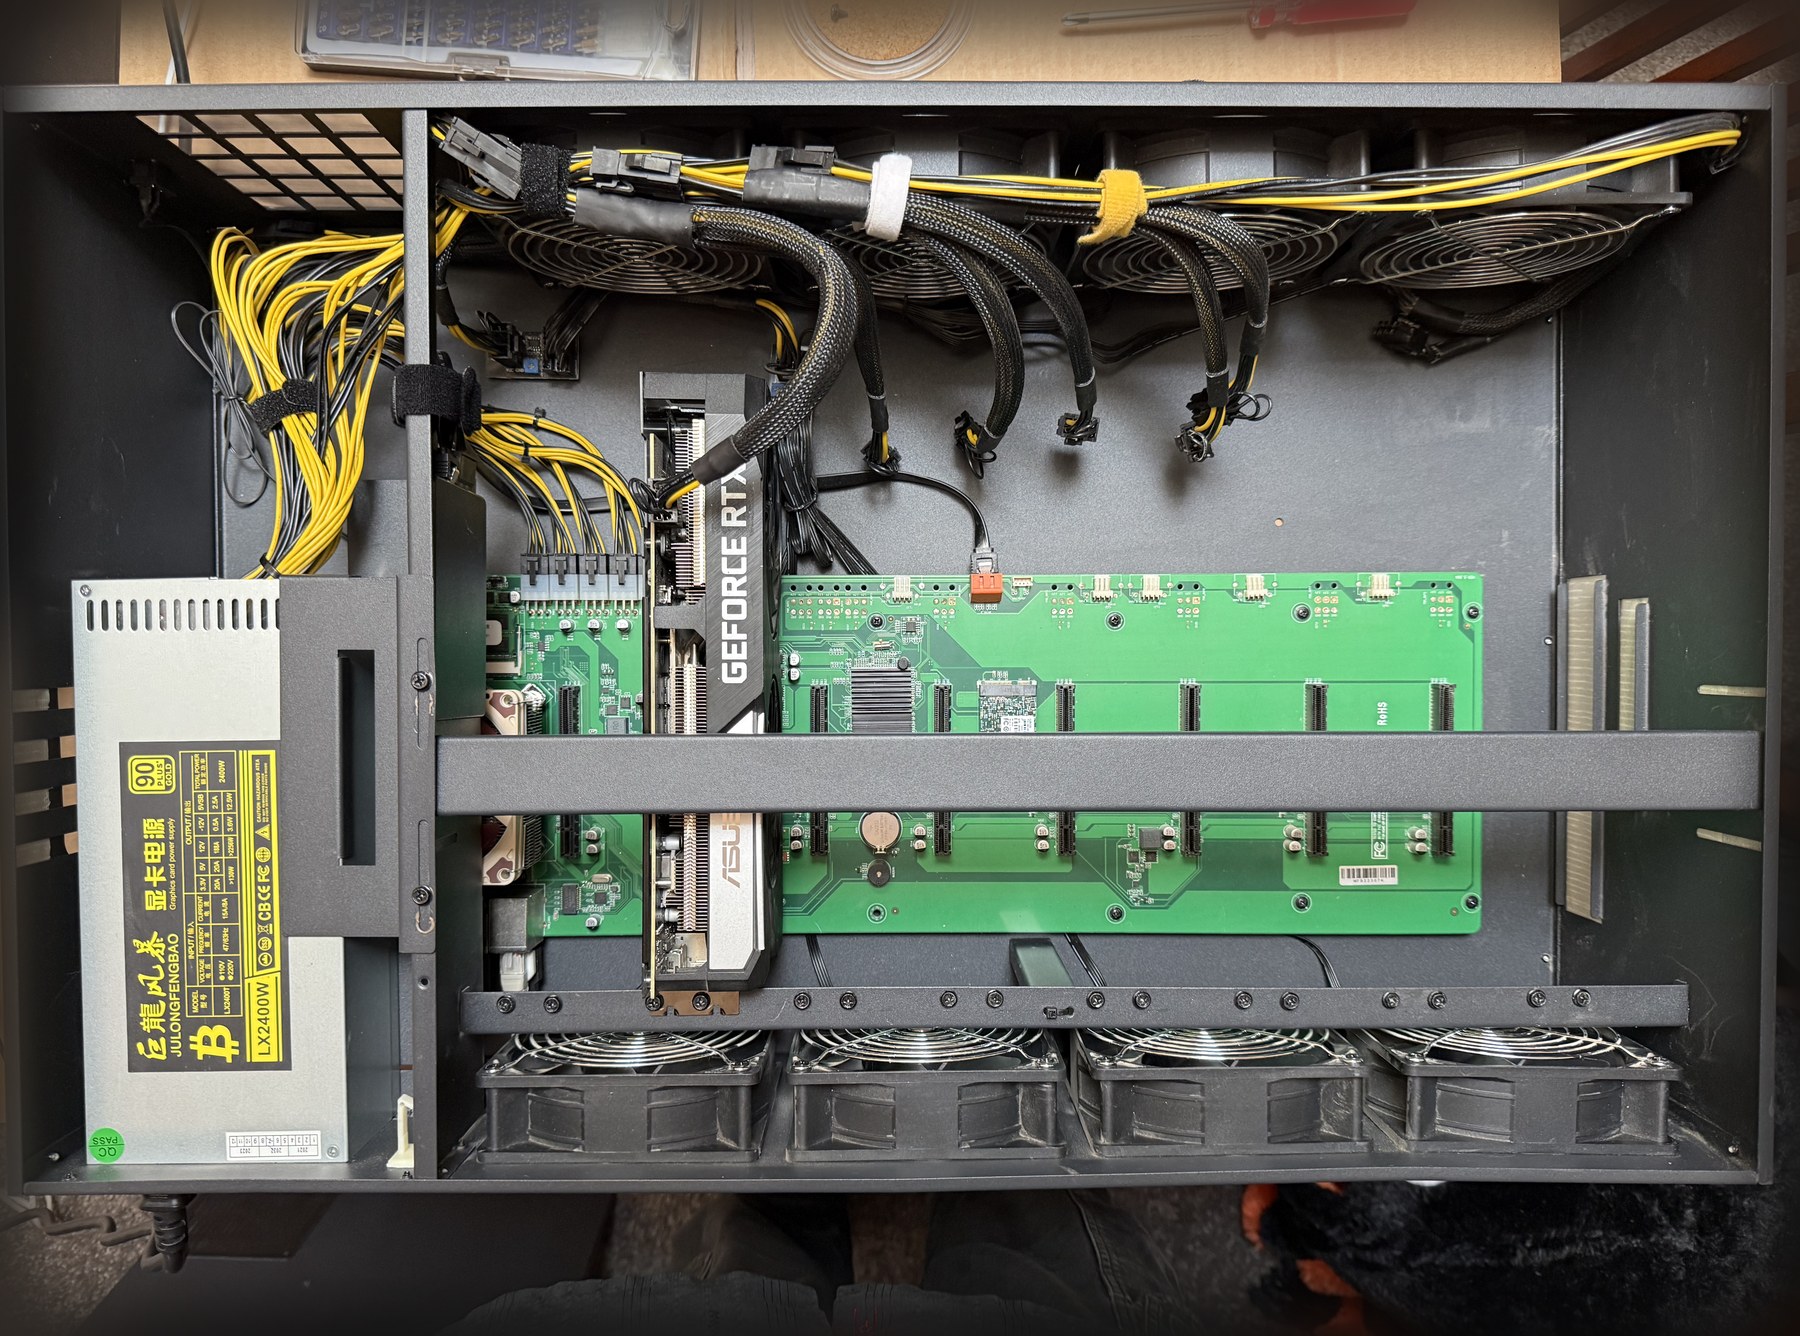 Era 9 • Jul 25
🔍 Embiggen
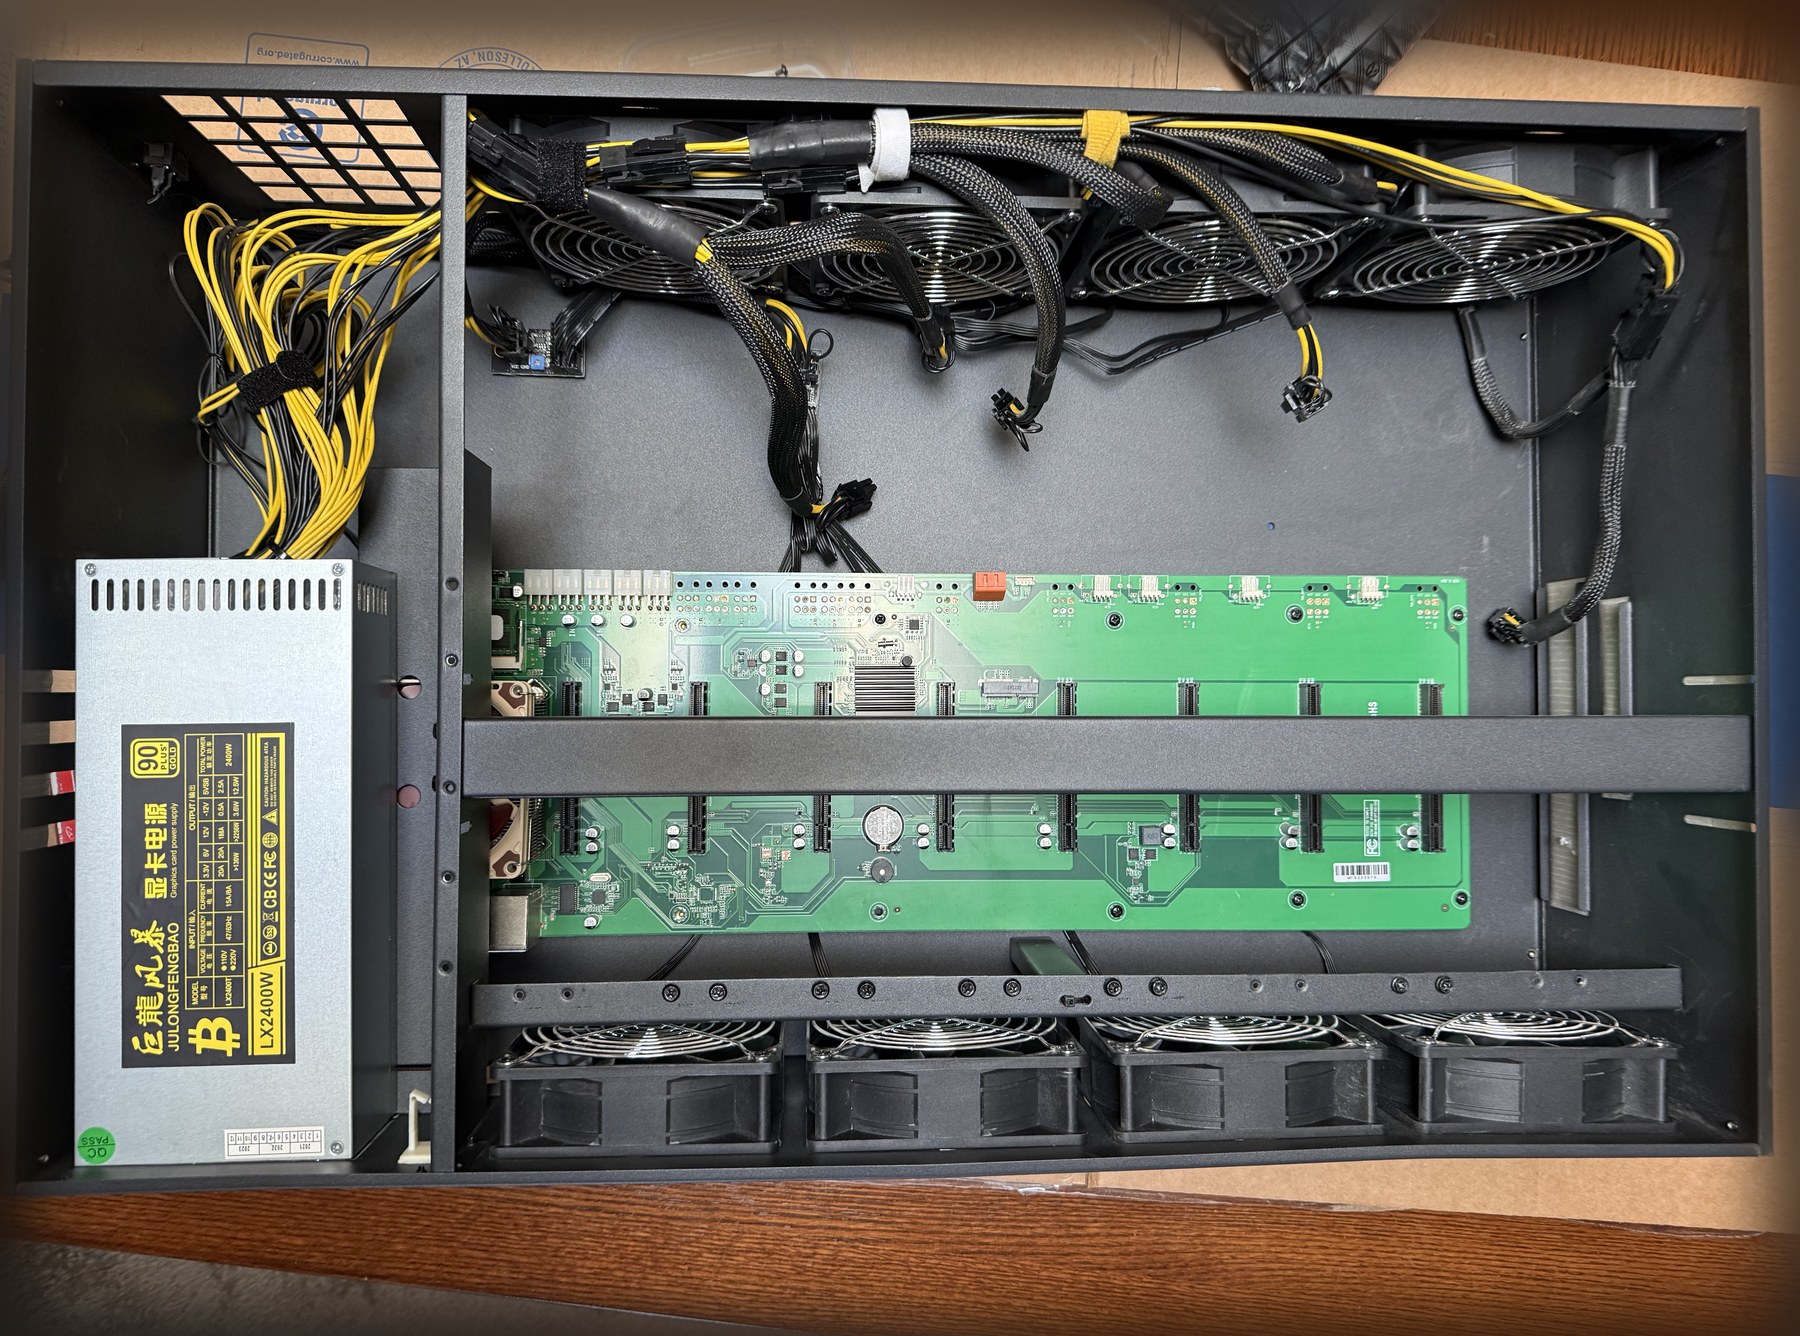 Era 9 • Jul 25
🔍 Embiggen
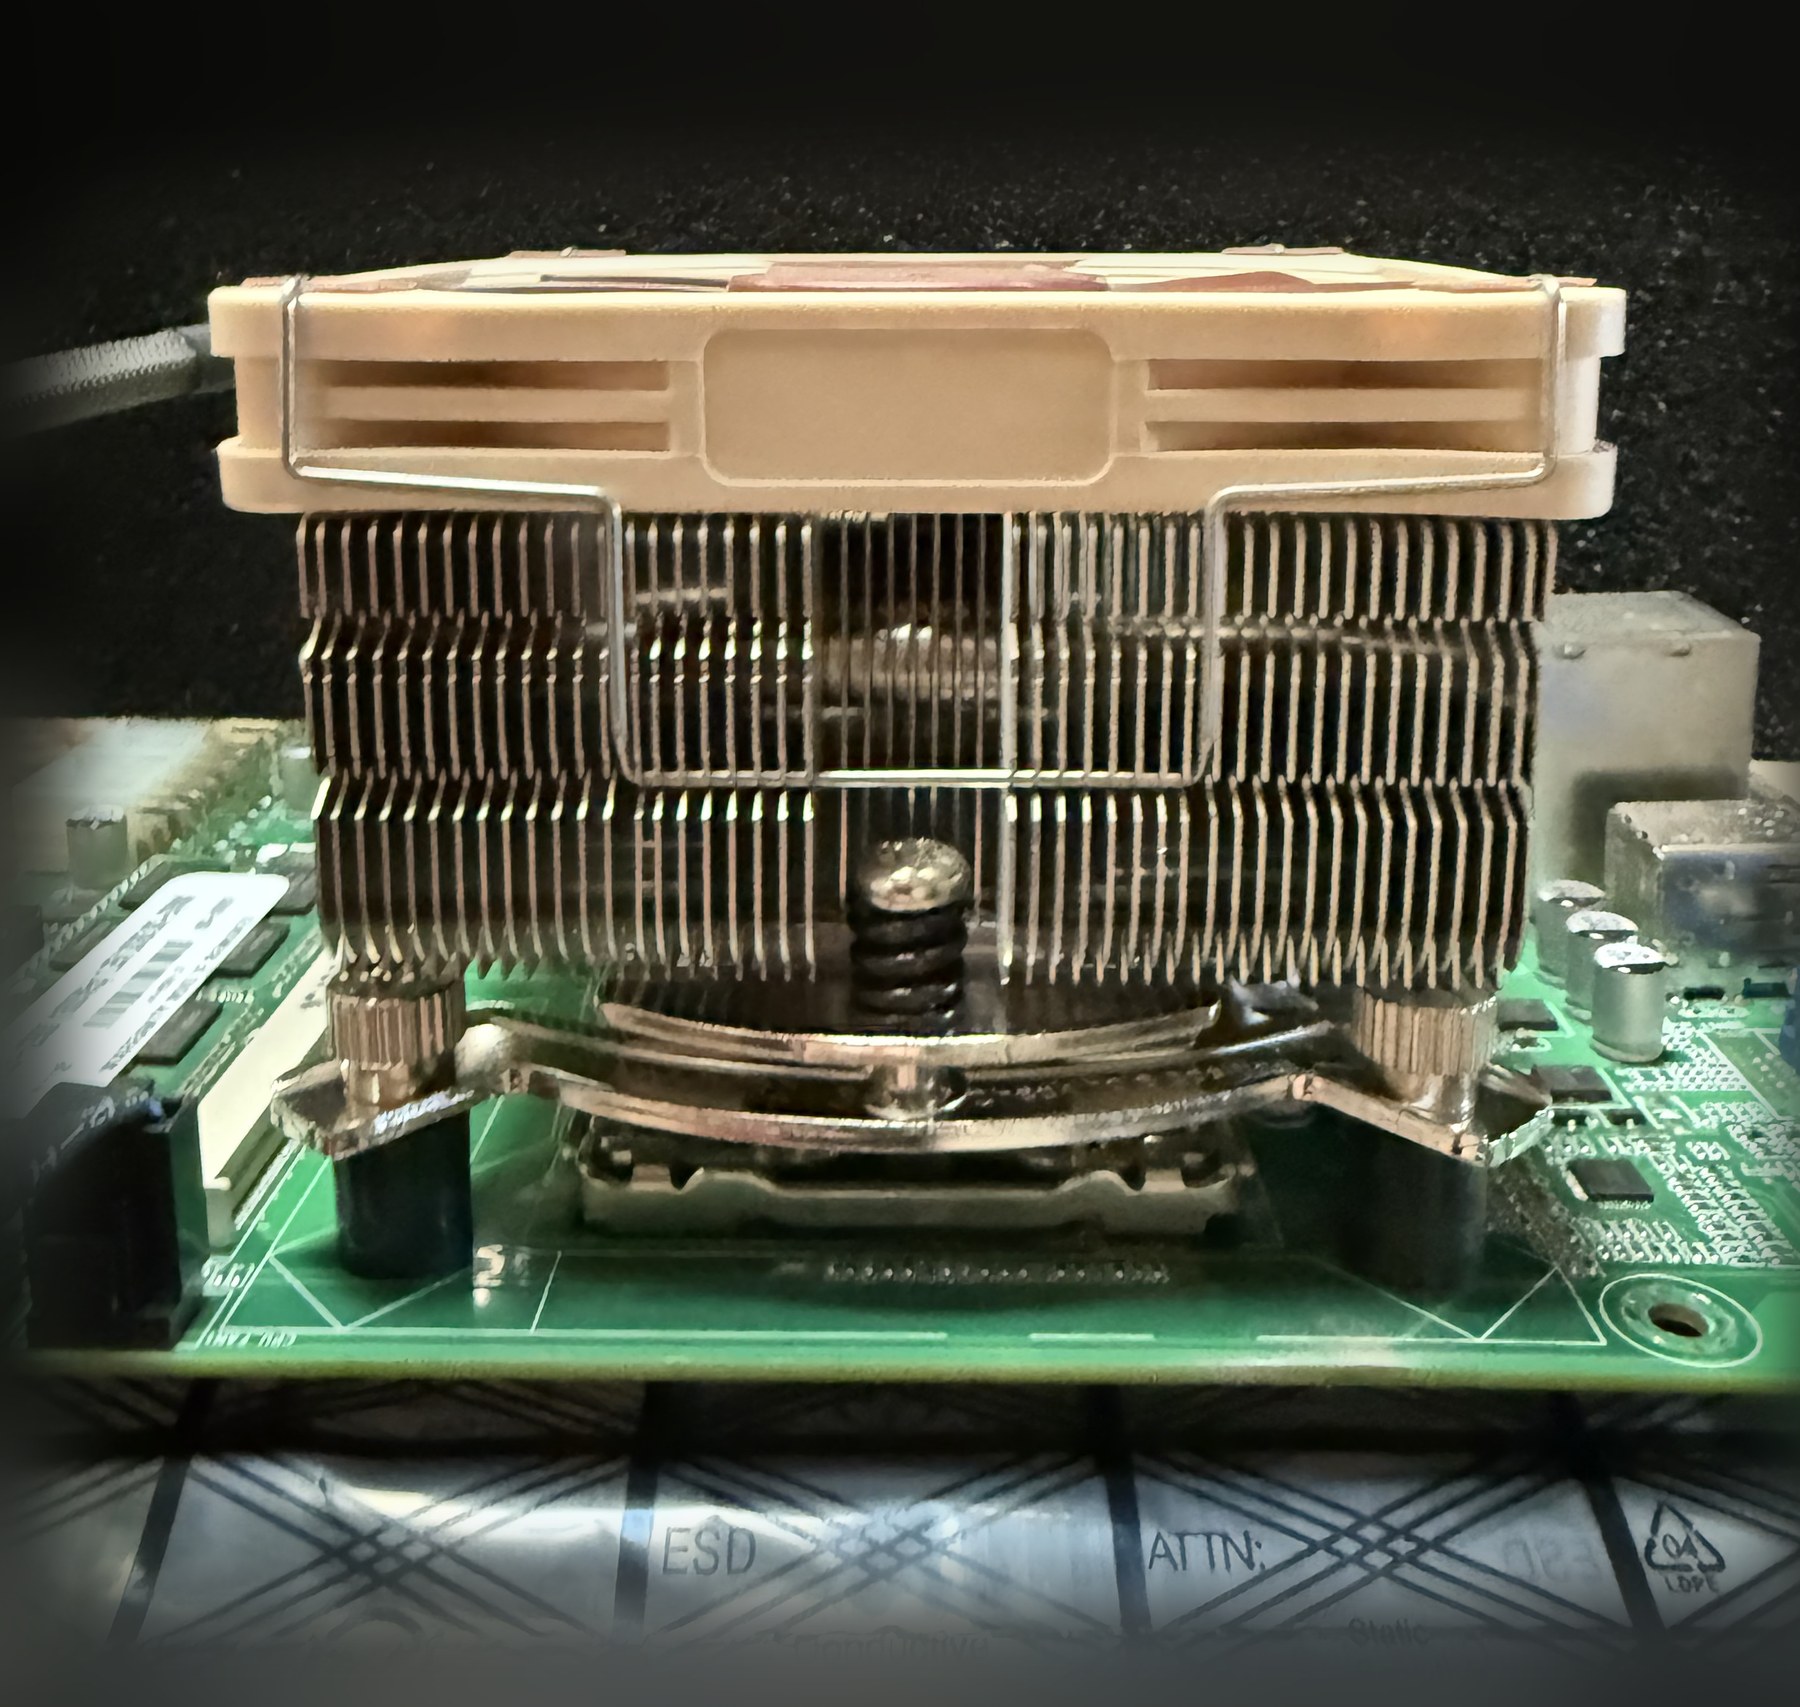 Era 9 • Jul 25
🔍 Embiggen
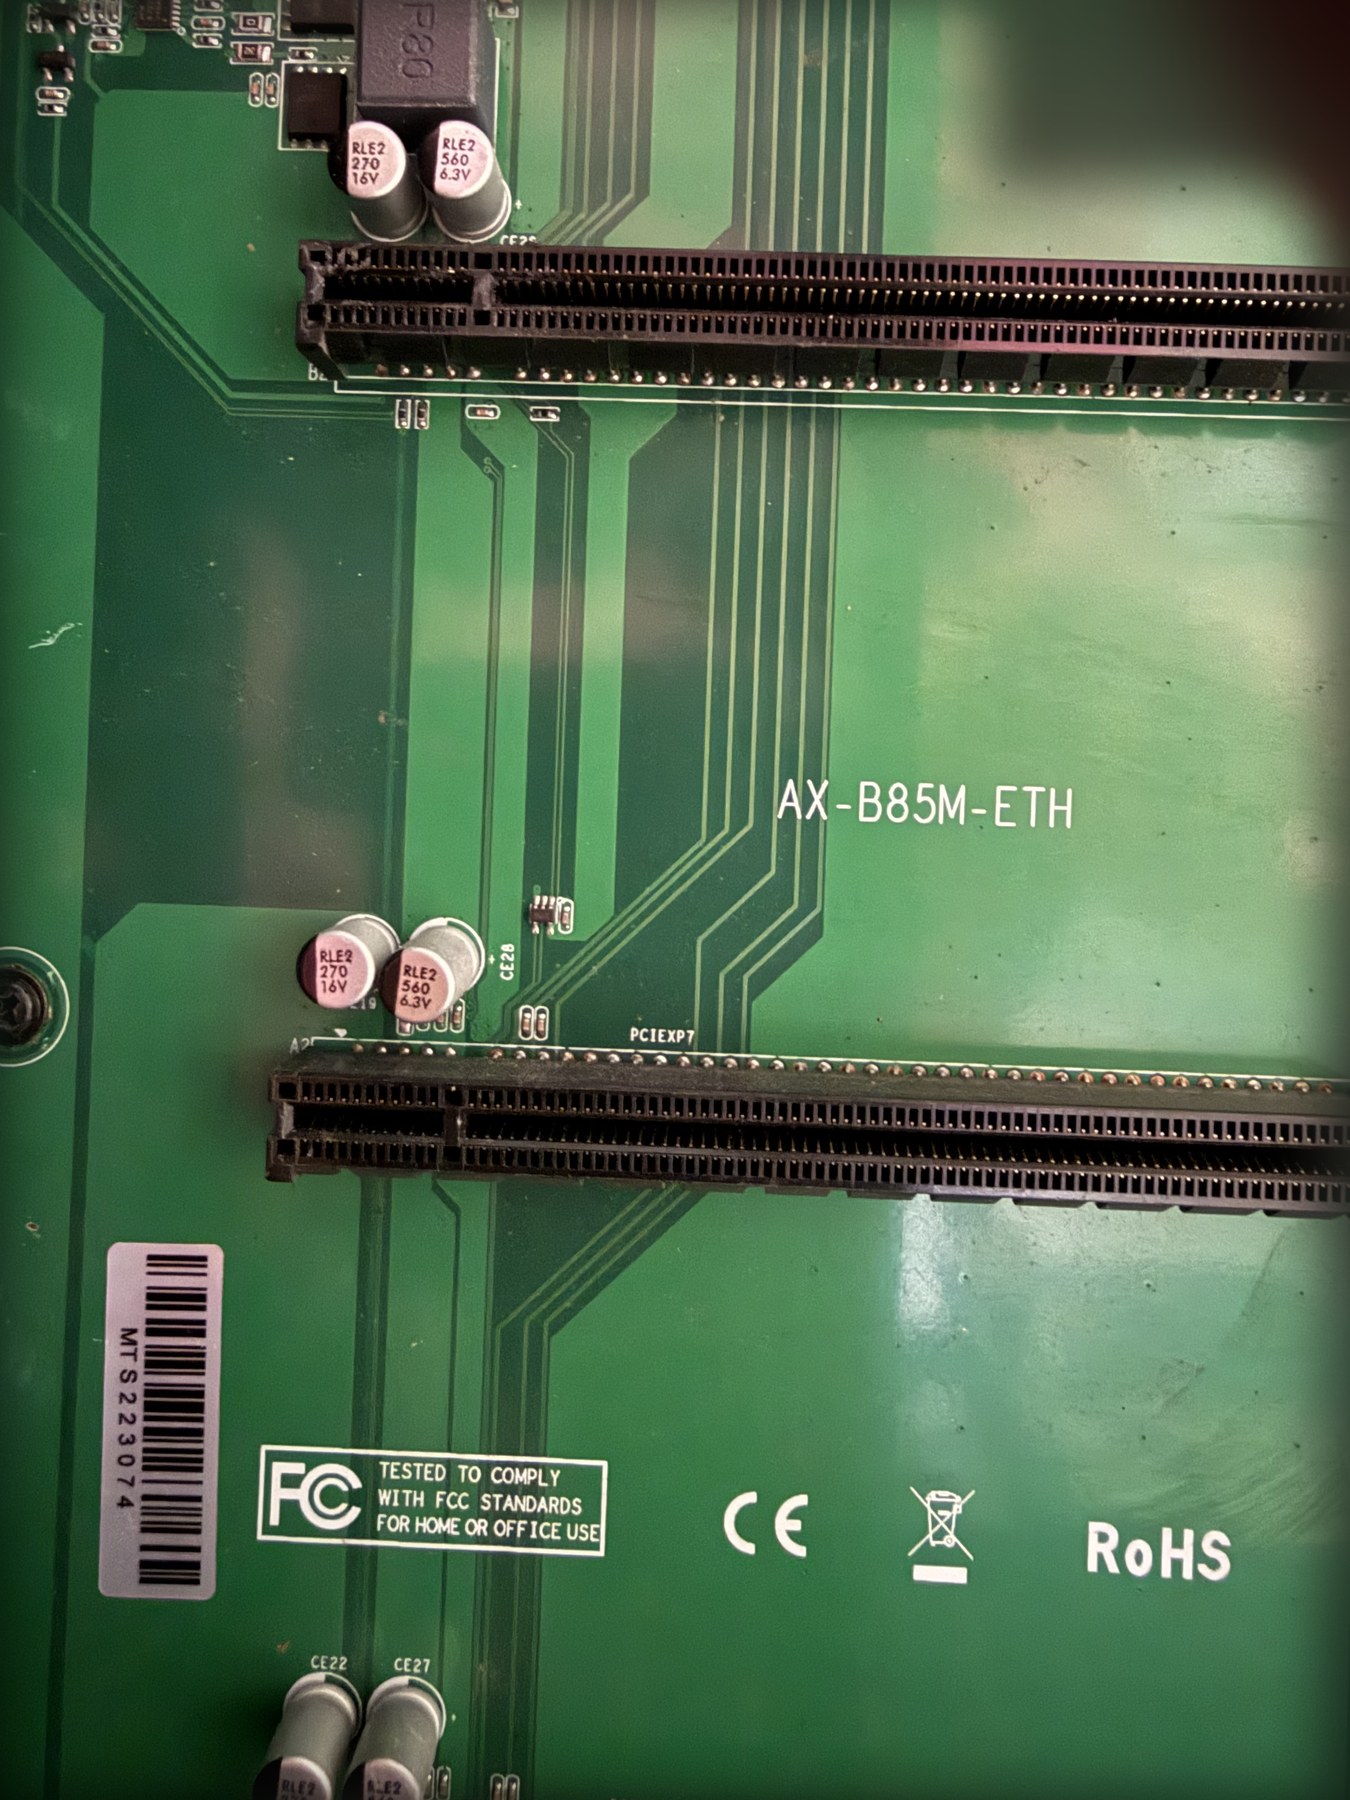 Era 9–12 • Jul 25–Oct 25
🔍 Embiggen
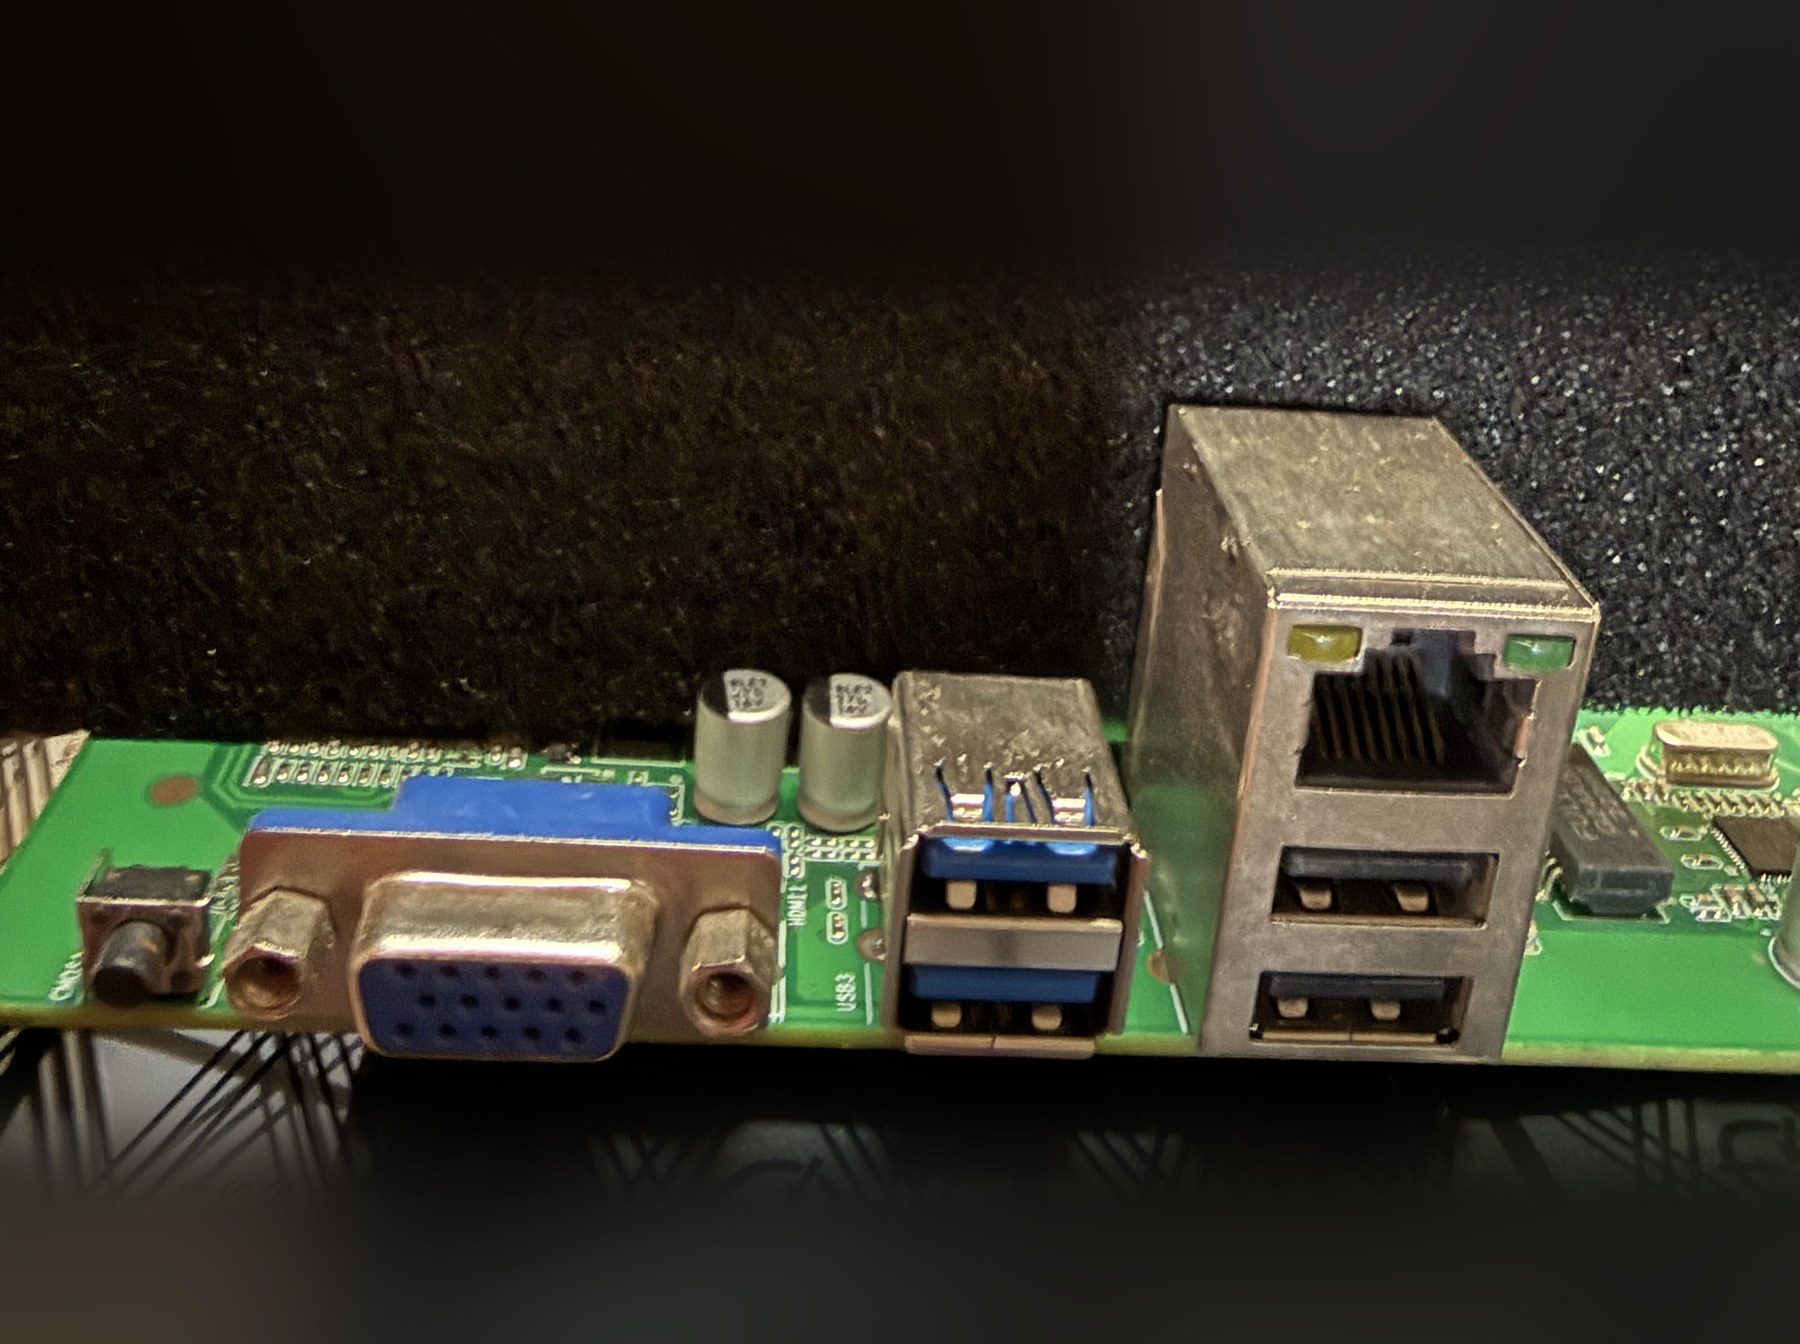 Era 9–12 • Jul 25–Oct 25
🔍 Embiggen
- Network Interface Normalization: Upon first boot inside the Octominer B250 motherboard, the onboard Realtek
RTL8105ENIC enumerated asenp3s0; updating Netplan restoredscrapsat its canonical static IP (10.42.42.27). - Historical
scrapsv1 (AX-B85M-ETH) Slot Map (Jul 25, 2026 – Oct 25, 2026):- GPNE Slot 1 (x1, Bus
02): DELL RTX 3060 Ti (1ed25c7d) → Migrated to OX12U Slot 4 (Bus06:00.0, GPU 4) - GPNE Slot 2 (x1, Bus
03): ASUS RTX 3060 Ti (a76d84a0) → Migrated to OX12U Slot 7 (Bus05:00.0, GPU 3) - GPNE Slot 4 (x1, Bus
04): ASUS RTX 3060 Ti (d1ea526f) → Migrated to OX12U Slot 10 (Bus02:00.0, GPU 1) - GPNE Slot 6 (x1, Bus
05): ASUS RTX 2060 (535ba65c, 6GB) → Idled Aug 29, 2026; Retired Oct 26, 2026 - GPNE Slot 8 (x1, Bus
06): Gigabyte RTX 2060 SUPER (8990101d, 8GB) → Idled Aug 29, 2026; Retired Oct 26, 2026
- GPNE Slot 1 (x1, Bus